Measurement & Verification in CAMBER (IPMVP / ASHRAE G14 / CalTRACK)
CAMBER implements whole-building IPMVP Option-C savings — equivalently the CalTRACK normalized metered energy consumption (NMEC) workflow — from standard parts: a weather-based baseline model, goodness-of-fit statistics, and avoided energy use with uncertainty. This page maps CAMBER's API to the CalTRACK/IPMVP vocabulary and shows how to cross-check against OpenEEmeter (eemeter), the reference open-source CalTRACK implementation.
IPMVP Option-C / CalTRACK NMEC pipeline: fit a weather baseline, project it onto reporting weather, and report avoided energy with an uncertainty band.
flowchart LR
    bl["Baseline (energy, temp)"] --> fit["best_model / towt"]
    fit --> gof["fit_stats: CV(RMSE), NMBE"]
    gof -- "G14 acceptance tier" --> avoided
    rep["Reporting (energy, temp)"] --> proj["Adjusted baseline"]
    fit -- "project onto reporting weather" --> proj
    proj --> cov["coverage: in range?"]
    cov -- "in_range / moderate (caveat, widen FSU)" --> avoided["avoided_energy_savings"]
    cov -- "severe" --> declined["Declined (no saving)"]
    avoided --> out["Savings + FSU band"]
    rep --> nre["detect_non_routine"]
    nre -- "exclude days and refit" --> fit
    avoided --> cusum["cusum tracking"]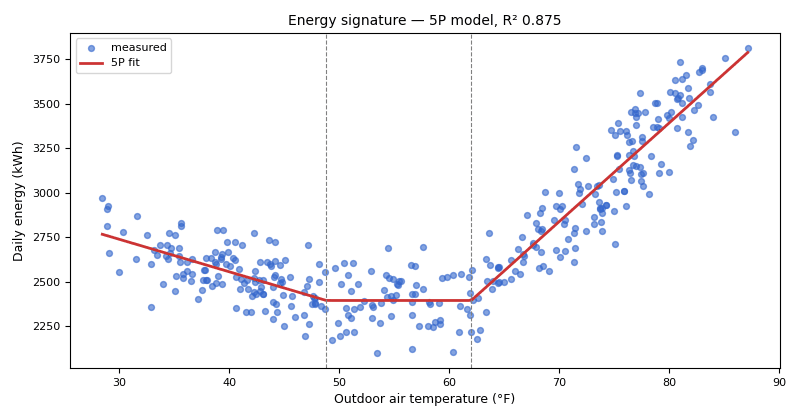
Synthetic data: a year of daily energy fitted by best_model, drawn with charts.energy_signature. The fit picked a five-parameter model: heating below about 49 °F, a flat base, cooling above about 62 °F.
Terminology bridge
| IPMVP / CalTRACK term | CAMBER |
|---|---|
| Baseline period / reporting period | the two (energy, temp) series you pass in |
| Baseline model | mandv.models.best_model (change-point 2P–5P) / mandv.towt (hourly) |
| Goodness of fit — CV(RMSE), NMBE | mandv.stats.fit_stats |
| Avoided energy use | mandv.stats.avoided_energy_savings |
| Fractional savings uncertainty (FSU) | G14 Annex-B, in the same call — t·1.26·CV·√((n/n′)(1+2/n)/m)/F |
| Autocorrelation correction | n′ = n(1−ρ)/(1+ρ); ρ from stats.lag1_autocorrelation, carried on FitStats.rho_lag1 |
| Normalized annual savings | drive the models with a typical year (mandv.weather TMY/EPW) |
| Live actual weather (any lat/lon) | weather_source.oat_reference — NASA POWER fetch, see WEATHER.md |
| Cumulative savings tracking | mandv.cusum |
| Baseline covers the reporting conditions | mandv.coverage.assess_coverage → Coverage (tier, shares outside, distance beyond) |
| Extrapolation disclosure / refusal | SavingsResult.coverage, .caveats, .declined, .declined_reason |
| Uncertainty widening for extrapolation | SavingsResult.fsu_extrapolation_factor (k, below) |
| Data sufficiency: what a refused baseline needs | mandv.sufficiency.InsufficientBaseline (a ValueError) → .need: required, available, shortfall, unit, days to collect; the config's daily decline carries it as metrics["data_needed"] (0.98) |
Method correspondence
Every M&V model kind, method and function, by the label CAMBER's reports show, the standard
name to report it under, the citation and the known differences from that standard. The
table is generated from the registry camber.mandv.names (by scripts/mv_names_doc.py), which
the reports, the mv_baseline summary and the chart legends read too; the kind codes in data
and JSON are unchanged. An empty standard name marks a CAMBER construct with no standard
counterpart. See Naming and citations for how to cite them.
Change-point models
| Label | CAMBER | Standard name | Citation | Differences |
|---|---|---|---|---|
| 2P | 2P, mandv.models.fit_model |
Two-parameter (2P) linear regression model | ASHRAE G14-2014; Kissock et al. 2003 (RP-1050 IMT) | — |
| 3P cooling | 3PC, mandv.models.fit_model |
Three-parameter cooling change-point model (3PC) | ASHRAE G14-2014; Kissock et al. 2003 (RP-1050 IMT) | Change points grid-searched over 40 points between the 5th and 95th temperature percentiles, slopes by least squares at each (the RP-1050 approach). best_model chooses among the kinds by BIC, a CAMBER choice (G14 and the IMT do not prescribe a selection criterion). |
| 3P heating | 3PH, mandv.models.fit_model |
Three-parameter heating change-point model (3PH) | ASHRAE G14-2014; Kissock et al. 2003 (RP-1050 IMT) | Change points grid-searched over 40 points between the 5th and 95th temperature percentiles, slopes by least squares at each (the RP-1050 approach). best_model chooses among the kinds by BIC, a CAMBER choice (G14 and the IMT do not prescribe a selection criterion). |
| 3P cooling, zero base (CAMBER) | 3PCZ, mandv.models.fit_model |
— | — | CAMBER extension, not a G14 / IMT model: the intercept is fixed at zero (no base load), so p counts the slope(s) and change point(s) only. Opt-in (not in best_model's default set). |
| 3P heating, zero base (CAMBER) | 3PHZ, mandv.models.fit_model |
— | — | CAMBER extension, not a G14 / IMT model: the intercept is fixed at zero (no base load), so p counts the slope(s) and change point(s) only. Opt-in (not in best_model's default set). |
| 4P | 4P, mandv.models.fit_model |
Four-parameter change-point model (4P) | ASHRAE G14-2014; Kissock et al. 2003 (RP-1050 IMT) | Change points grid-searched over 40 points between the 5th and 95th temperature percentiles, slopes by least squares at each (the RP-1050 approach). best_model chooses among the kinds by BIC, a CAMBER choice (G14 and the IMT do not prescribe a selection criterion). |
| 5P | 5P, mandv.models.fit_model |
Five-parameter change-point model (5P) | ASHRAE G14-2014; Kissock et al. 2003 (RP-1050 IMT) | Both change points grid-searched on the same 40-point grid, the dead-band at least one grid step wide. When no dead-band fits, the fit falls back to a 2P line and keeps kind "5P" with no change points; it is then labelled "2P (5P fallback)". best_model chooses among the kinds by BIC, a CAMBER choice (G14 and the IMT do not prescribe a selection criterion). |
| 5P heating and cooling, zero base (CAMBER) | 5PZ, mandv.models.fit_model |
— | — | CAMBER extension, not a G14 / IMT model: the intercept is fixed at zero (no base load), so p counts the slope(s) and change point(s) only. Opt-in (not in best_model's default set). Falls back to a 2P line (with an intercept) like 5P: "2P (5P zero-base fallback)". |
| daily change-point (2P–5P, BIC) | mandv.models.best_model |
Change-point regression model (ASHRAE Guideline 14 / RP-1050 IMT), selected by BIC | ASHRAE G14-2014; Kissock et al. 2003 (RP-1050 IMT) | Fits 2P, 3PC, 3PH, 4P and 5P and keeps the lowest BIC, n ln(SSE/n) + p ln(n), with every change point counted in p; the model it returns is one of those kinds. |
Degree-day models
| Label | CAMBER | Standard name | Citation | Differences |
|---|---|---|---|---|
| Degree-day heating | DD-H, mandv.basetemp.fit_bill_degree_day |
Variable-base degree-day (VBDD) heating model, PRISM heating-only form | Fels 1986 (PRISM); Kissock et al. 2003 (RP-1050 IMT) | Daily degree-days summed over each bill, the base chosen from a grid by days-weighted least squares with a profile-likelihood range (select_bases); with a numeric base_f the base is fixed (a fixed-base degree-day model, base not counted in p). |
| Degree-day cooling | DD-C, mandv.basetemp.fit_bill_degree_day |
Variable-base degree-day (VBDD) cooling model | Fels 1986 (PRISM); Kissock et al. 2003 (RP-1050 IMT) | The cooling analogue of DD-H (PRISM's original model is heating-only); same base search. |
| Degree-day heating and cooling | DD-HC, mandv.basetemp.fit_bill_degree_day |
Variable-base degree-day (VBDD) heating-and-cooling model | Fels 1986 (PRISM); Kissock et al. 2003 (RP-1050 IMT) | Separate heating and cooling bases (heating base no higher than the cooling base), each searched on its own grid; p counts both fitted bases. |
| Degree-day on period-mean temperature (CAMBER) | degreeday, mandv.degreeday.fit_mean_temp_degree_day |
— | — | Not a variable-base degree-day (PRISM) model: degree-days come from each period's mean temperature, about one balance point shared by both legs, so a shoulder month's swing days are undercounted. The searched balance point is counted in p (since 0.105). Renamed in 0.105 from fit_degree_day / DegreeDayModel (deprecated aliases). |
Other baseline models
| Label | CAMBER | Standard name | Citation | Differences |
|---|---|---|---|---|
| TOWT (CAMBER variant) | towt, mandv.towt.fit_towt |
Time-of-Week-and-Temperature (TOWT) model (Mathieu et al. 2011; LBNL RMV2.0) | Mathieu et al. 2011; LBNL RMV2.0; Granderson et al. 2015; LBNL-187225; LBNL-6963E | One pooled model over the baseline; hour-of-week bins (168); by default n_temp_segments quantile-spaced temperature knots held flat beyond the fitted range rather than the reference's fixed knots; occupancy from each bin's mean load against the median of bin means; no time-weighting of observations. Opt-in (0.105): towt_lbnl_config() matches RMV2.0's knots (40, 55, 65, 80, 90 degF, open outer segments, outer knots pruned under 20 observations), its zero clip and its recency weight function (fit_towt(weights=lbnl_time_weights(...))); it still fits one weighted model with load-median occupancy, in hour-of-week bins where RMV2.0 defaults to 15-minute intervals (the same on hourly data), and refuses (or, opt-in, fills) an unseen time of week where RMV2.0 predicts NaN. RMV2.0's 65% positive-residual occupancy rule and its ensemble of local fits are in towt_rmv2 (fit_towt_rmv2). |
| TOWT (LBNL RMV2.0 variant) | towt_rmv2, mandv.towt_rmv2.fit_towt_rmv2 |
Time-of-Week-and-Temperature (TOWT) model (Mathieu et al. 2011) | LBNL RMV2.0; Mathieu et al. 2011 | Opt-in (0.105). Reproduces RMV2.0 1.1.0's makeBaseline (R/towt_baseline.R, commit 979a963): its occupancy rule (a regression of load on temperature hinged at 50 and 65 degF; an interval is occupied when over 65% of its residuals are positive, and the split needs more than two), its knots and pruning, and its ensemble of local fits centred every ~14 days by row count, each prediction clipped at zero and averaged with the weights s^2/(s^2+dt^2) about the prediction time. An unseen time of week is NaN. Differences: hour-of-week intervals by default (RMV2.0: 15 minutes, the same on hourly data); RMV2.0's data cleaning (clean_eload, clean_Temp) is not applied, CAMBER's temperature screen is; the final approx() fill of NaN is opt-in (unseen="previous"). Differs from Mathieu et al. (2011): data-driven occupancy and time weighting. As in RMV2.0, a prediction leans on the local fits centred nearest it, in the reporting period those at the end of the baseline: suited to short horizons and to tracking recent conditions; several months ahead, in a season the baseline saw little of, it can be less accurate than unweighted TOWT. |
| Change-point + drivers (multivariable) | multivariable, mandv.multivariable.fit_cp_driver_model |
Multivariable change-point regression model (SEP 50001 M&V Protocol §6.3.2) | SEP 50001 M&V Protocol 2019; ASHRAE G14-2014 | Change points grid-searched with the drivers in the design; drivers enter linearly. |
| Categorical change-point (one model per category) | categorical, mandv.categorical.fit_categorical |
— | ASHRAE G14-2014 | A CAMBER construct: a separate change-point model per category combination (day type, occupancy mode), routed by category, with pooled fit statistics; not indicator terms in one regression. |
Savings methods (SEP 50001 M&V Protocol §6.2; the config's mv.method)
| Label | CAMBER | Standard name | Citation | Differences |
|---|---|---|---|---|
| Forecast (avoided energy) | forecast, mandv.methods.forecast_savings |
Forecast method (SEP 50001 M&V Protocol §6.2.1); IPMVP avoided energy use | SEP 50001 M&V Protocol 2019; IPMVP Core Concepts 2022 | — |
| Backcast | backcast, mandv.methods.backcast_savings |
Backcast method (SEP 50001 M&V Protocol §6.2.2) | SEP 50001 M&V Protocol 2019 | — |
| Standard conditions (normalized savings) | standard_conditions, mandv.methods.standard_conditions_savings |
Standard conditions method (SEP 50001 M&V Protocol §6.2.3); IPMVP normalized savings | SEP 50001 M&V Protocol 2019; IPMVP Core Concepts 2022 | — |
| Chaining | chaining, mandv.methods.chained_savings |
Chaining method (SEP 50001 M&V Protocol §6.2.4) | SEP 50001 M&V Protocol 2019 | — |
| Sequential chain (CAMBER extension) | mandv.methods.sequential_chain |
— | — | A multi-link chain; the SEP Protocol defines exactly one intermediate period. |
| Method proposal (SEP order) | auto, mandv.methods.select_method |
— | SEP 50001 M&V Protocol 2019 | Proposes a method in the SEP order and ranks models by SEP validity then adjusted R² (the DOE EnPI tool's order). It proposes a method; it computes no saving itself. |
IPMVP options
| Label | CAMBER | Standard name | Citation | Differences |
|---|---|---|---|---|
| IPMVP Option A (key-parameter measurement) | option_a, mandv.option_a.option_a_savings |
IPMVP Option A: retrofit isolation, key parameter measurement | IPMVP Core Concepts 2022 | The uncertainty of the stipulated portion is not quantified. |
| IPMVP Option B (retrofit isolation) | retrofit_isolation, mandv.retrofit_isolation.isolation_savings |
IPMVP Option B: retrofit isolation, all parameter measurement | IPMVP Core Concepts 2022; ASHRAE G14-2014 | — |
| Normalized savings | normalized, mandv.normalized.normalized_savings |
IPMVP normalized savings (standard conditions) | IPMVP Core Concepts 2022; SEP 50001 M&V Protocol 2019 | — |
| Option D-style modeled savings (calibrated 1R1C grey box; pre-implementation estimate) | option_d, mandv.rc_model.option_d_savings |
IPMVP Option D: calibrated simulation | IPMVP Core Concepts 2022; ASHRAE G14-2014 | A calibrated grey-box RC model (1R1C, or 2R2C / multi-zone), not a whole-building simulation program, used before implementation to estimate a control change. The calibration gate is fit_stats: CV(RMSE) by interval (30 % hourly), |NMBE| <= 0.5 % and R² >= 0.75, all required. |
Whole-building savings functions
| Label | CAMBER | Standard name | Citation | Differences |
|---|---|---|---|---|
| CalTRACK 2.0 Daily | mandv.caltrack_daily.caltrack_daily_savings |
CalTRACK 2.0 Daily method | CalTRACK 2.0 | Model CalTRACKDailyModel (fit_caltrack_daily). Defaults follow the CalTRACK 2.0 documents (3 °F balance-point grid, at most 37 missing days, day usage kept at >= 50 % coverage, <= 6 h temperature gaps interpolated); eemeter_compat=True reproduces eemeter 2.10 where the two differ (1 °F grid and the rest). The degree days of a period are the mean over its days with a valid temperature (eemeter's reading). The savings band is CAMBER's G14 band; CalTRACK's own FSU is reported beside it. |
| CalTRACK 2.0 Billing | mandv.caltrack_daily.caltrack_billing_savings |
CalTRACK 2.0 Billing method | CalTRACK 2.0 | Model CalTRACKBillingModel (fit_caltrack_billing): the daily model fitted to bills' usage per day by WLS weighted by the bill's days with a valid temperature (eemeter's weight; the documents' n_p is equal when temperature is complete). Estimated reads are combined with the next bill up to 70 days (eemeter does not cap). eemeter_compat=True reproduces eemeter 2.10. |
| CalTRACK 2.0 Hourly | mandv.caltrack_hourly.caltrack_hourly_savings |
CalTRACK 2.0 Hourly method (CalTRACK TOWT) | CalTRACK 2.0; Mathieu et al. 2011 | Model CalTRACKHourlyModel (fit_caltrack_hourly). An hour of the week that a month's segment never saw predicts NaN in both modes (eemeter 3.1's fix; eemeter 2.10 predicts the temperature terms alone there). The > 90 % monthly coverage rule is applied (a stub in eemeter 2.10, skipped under eemeter_compat=True). CalTRACK publishes no hourly FSU, so only the G14 band is reported. |
| Daily change-point savings (not CalTRACK) | mandv.caltrack.daily_changepoint_savings |
— | ASHRAE G14-2014; IPMVP Core Concepts 2022 | Not CalTRACK 2.0 Daily: a best_model daily change-point baseline (2P–5P, BIC) with IPMVP avoided energy and a G14 band, without CalTRACK's candidate models, balance-point grid, qualifying tests, adjusted-R² selection or data-sufficiency rules. Called caltrack_savings before 0.105 (#156). |
| Pooled TOWT hourly savings (not CalTRACK Hourly) | mandv.caltrack.towt_savings_hourly |
— | Mathieu et al. 2011 | Not CalTRACK 2.0 Hourly: one pooled TOWT (CAMBER variant) model, not per-month segmented models with fixed temperature bins and a residual-based occupancy lookup. Called caltrack_savings_hourly before 0.105 (#156). |
| Daily change-point savings (not CalTRACK; deprecated name) | mandv.caltrack.caltrack_savings |
— | ASHRAE G14-2014; IPMVP Core Concepts 2022 | Deprecated alias (0.105, removed in 1.0) of daily_changepoint_savings, same numbers; not CalTRACK 2.0 Daily, which is caltrack_daily_savings (#156). |
| Pooled TOWT hourly savings (not CalTRACK Hourly; deprecated name) | mandv.caltrack.caltrack_savings_hourly |
— | Mathieu et al. 2011 | Deprecated alias (0.105, removed in 1.0) of towt_savings_hourly, same numbers; not CalTRACK 2.0 Hourly, which is caltrack_hourly_savings (#156). |
Tracking and forecasting
| Label | CAMBER | Standard name | Citation | Differences |
|---|---|---|---|---|
| CUSUM of savings | cusum, mandv.cusum.cusum_savings |
Cumulative sum (CUSUM) of savings | — | Common M&V tracking practice; no single standard defines it, so none is cited. |
| Mean-Week + drift (LBNL M4 analogue), not an M&V method | forecast.seasonal_forecast |
— | Granderson et al. 2015; LBNL-187225; LBNL-6963E | A load forecast for anomaly detection, not an M&V baseline: the mean of history at each time-of-week slot (the LBNL test reports' Mean-Week model) plus an additive drift correction from the recent residuals. No weather term. |
References
ashrae-g14-2014: ASHRAE Guideline 14-2014, Measurement of Energy, Demand, and Water Savings. Guideline 14-2014. ASHRAE. https://www.ashrae.org/technical-resources/standards-and-guidelines/titles-purposes-and-scopesashrae-rp1050-imt: Kissock, J.K., Haberl, J.S., Claridge, D.E. (2003). Inverse Modeling Toolkit: Numerical Algorithms (ASHRAE RP-1050). ASHRAE Transactions 109(2). KC-03-02-1. https://iifiir.org/en/fridoc/inverse-modelling-toolkit-imt-numerical-algorithms-22451fels-1986-prism: Fels, M.F. (1986). PRISM: An introduction. Energy and Buildings 9(1-2):5-18. doi:10.1016/0378-7788(86)90003-4. https://doi.org/10.1016/0378-7788(86)90003-4mathieu-2011-towt: Mathieu, J.L., Price, P.N., Kiliccote, S., Piette, M.A. (2011). Quantifying Changes in Building Electricity Use, With Application to Demand Response. IEEE Transactions on Smart Grid 2(3):507-518. LBNL-4944E. doi:10.1109/TSG.2011.2145010. https://www.osti.gov/biblio/1048308lbnl-rmv2: Touzani, S. (2017). RMV2.0: an R package for measurement and verification 2.0 (towt_baseline, version 1.1.0). https://github.com/LBNL-ETA/RMV2.0granderson-2015-baselines: Granderson, J., Price, P.N., Jump, D., Addy, N., Sohn, M.D. (2015). Automated measurement and verification: Performance of public domain whole-building electric baseline models. Applied Energy 144:106-113. LBNL-187596. doi:10.1016/j.apenergy.2015.01.026. https://www.osti.gov/pages/biblio/1247594lbnl-187225: Granderson, J., Touzani, S., Custodio, C., Sohn, M.D., Fernandes, S., Jump, D. (2015). Assessment of Automated Measurement and Verification (M&V) Methods. LBNL-187225. doi:10.2172/1236174. https://www.osti.gov/biblio/1236174lbnl-6963e: Granderson, J., Jump, D., Price, P.N., Sohn, M.D. (2014). Performance Metrics and Objective Testing Methods for Energy Baseline Modeling Software. 2014 ACEEE Summer Study on Energy Efficiency in Buildings, paper 11-734. LBNL-6963E. https://www.aceee.org/wp-content/uploads/proceedings-1980-2020/2014/11-734.pdfcaltrack-2: CalTRACK Technical Documentation: Methods (CalTRACK 2.0). CalTRACK (LF Energy OpenEEmeter). https://docs.caltrack.org/en/latest/methods.htmlevo-ipmvp-core-2022: International Performance Measurement and Verification Protocol (IPMVP) Core Concepts 2022. EVO 10000-1:2022. Efficiency Valuation Organization (EVO). https://evo-world.org/en/products-services-mainmenu-en/protocols/ipmvpdoe-sep-mv-2019: Superior Energy Performance 50001 Program Measurement & Verification Protocol: 2019 (Edition 2). U.S. Department of Energy. https://betterbuildingssolutioncenter.energy.gov/iso-50001/sep-50001/resources/sep-50001-measurement-and-verification-protocol
CalTRACK 2.0 and CAMBER's own whole-building baselines. caltrack_daily_savings,
caltrack_billing_savings and caltrack_hourly_savings implement the CalTRACK 2.0 methods as
published, with eemeter_compat=True to reproduce eemeter 2.10 (see
CalTRACK 2.0 methods). daily_changepoint_savings and
towt_savings_hourly are CAMBER's own baselines, not CalTRACK: a daily change-point model
(best_model, 2P–5P by BIC) and a pooled TOWT, each with IPMVP avoided energy and a G14 band.
They were called caltrack_savings and caltrack_savings_hourly before 0.105; those names are
deprecated aliases with the same numbers (#156). The pooled TOWT differs from CalTRACK Hourly:
CalTRACK Hourly (caltrack_hourly_savings) |
CAMBER mandv.towt (towt_savings_hourly) |
|---|---|
| per-calendar-month segmented models, weighted | one pooled model over the baseline |
| six fixed temperature bin edges | n_temp_segments quantile-spaced breakpoints |
| occupancy from an hour-of-week lookup per month, from a preliminary model's residuals | occupancy from bin-mean load vs the median of bin means |
| > 90 % of each month's hours, per month segment | hour count plus per-hour-of-week-bin coverage |
Expect an hourly band comparable to the daily method, not tighter. Hourly residuals are strongly serially correlated (ρ≈0.85 is ordinary), and the effective-sample-size correction bites: measured on a 20-week synthetic, n=3360 hours becomes n_eff=282 and the band widens from 1.6% at ρ=0 to 9.7% at ρ=0.85. Finer data does not buy proportionally more certainty.
Billing/monthly data use the same change-point models on monthly data (the looser CV(RMSE)
tier), fitted per bill and weighted by days, or the variable-base degree-day models of
mandv.basetemp (see Billing data).
Naming and citations
When a report, a testing portal or an evaluator asks for the model type, give the standard name from the table above, with its citation, and the CAMBER label beside it. The registry has the same text for code to read:
from camber.mandv.names import citations, model_label, mv_name

row = mv_name("3PC")
row.standard_name  # 'Three-parameter cooling change-point model (3PC)'
row.differences  # where CAMBER's fit departs from the cited standard
[r.citation() for r in citations("3PC")]  # ASHRAE G14-2014; Kissock et al. 2003 (RP-1050 IMT)
model_label(model)  # a fitted model's label, e.g. '2P (5P fallback)'
- Name the fitted kind, not the search.
best_modelreports the kind it chose; cite that kind by its own standard name ("three-parameter cooling change-point model (3PC), ASHRAE Guideline 14 / RP-1050 IMT, selected among 2P–5P by BIC"), not "CAMBER best model".model_label(model)andmv_name(model.kind)give the chosen kind's row. - State the differences. A row with differences is reported under the standard name with them ("TOWT (Mathieu et al. 2011), CAMBER variant: quantile-spaced temperature knots, hour-of-week bins, load-median occupancy"), or under the CAMBER label alone.
- No standard name, no borrowed one. A CAMBER construct (the zero-base kinds, the period-mean
degree-day model, the sequential chain) is named by its label and described; it is not called
the nearest standard model.
daily_changepoint_savingsandtowt_savings_hourly(and their deprecated old namescaltrack_savings/caltrack_savings_hourly) are not CalTRACK: name what they fit.caltrack_daily_savings,caltrack_billing_savingsandcaltrack_hourly_savingsare CalTRACK 2.0 Daily, Billing and Hourly. - An ensemble is its components. A prediction that combines several models is described as
"Ensemble approach combining" each component's standard name, then the combination rule.
ensemble_description(components, rule)incamber.mandv.namesbuilds the sentence from the registry rows (codes, fitted models or theiras_dictpayloads), so the names and citations match the table above:
from camber.mandv.names import ensemble_description

ensemble_description(["3PC", "towt"], "the prediction is the unweighted mean of the two")
# 'Ensemble approach combining a three-parameter cooling change-point model (3PC) [ASHRAE
# G14-2014] and a Time-of-Week-and-Temperature (TOWT) model (Mathieu et al. 2011; LBNL
# RMV2.0), CAMBER variant [Mathieu et al. 2011]; the prediction is the unweighted mean of the
# two.'
Give the weights or the selection rule exactly; a name such as "CAMBER ensemble" alone is not
a model type. cite="all" lists every citation of each row, cite="none" none.
- Choose the variable-base form for bills. The period-mean degree-day model (degreeday) is
not a variable-base degree-day model; for VBDD on bills use mandv.basetemp (DD-H, DD-C,
DD-HC).
- Differences paste verbatim. Each row's differences text only describes where CAMBER
departs from the cited standard (no instructions), so it can go into a report as it is.
- A proposal is not a method. select_method (auto) proposes a method; a reported saving
names the method it declared.
- Cite the method too. The savings method has its own name (forecast / avoided energy,
backcast, standard conditions / normalized savings, chaining; SEP 50001 M&V Protocol §6.2,
IPMVP), and so does the uncertainty band (ASHRAE Guideline 14 Annex B for the measured kernel,
and the daily 30 % CV(RMSE) tier is CAMBER's interpolation, not a G14 value).
Quick use
from camber.mandv.caltrack import daily_changepoint_savings

res = daily_changepoint_savings(
    baseline_energy, baseline_temp, reporting_energy, reporting_temp
)  # hourly Series in
print(res.model_kind, round(res.baseline_r2, 3))
print(res.savings.savings_pct, "±", res.savings.fractional_uncertainty)  # fractions
print(res.savings.coverage["tier"], res.savings.caveats)  # did the baseline cover it?
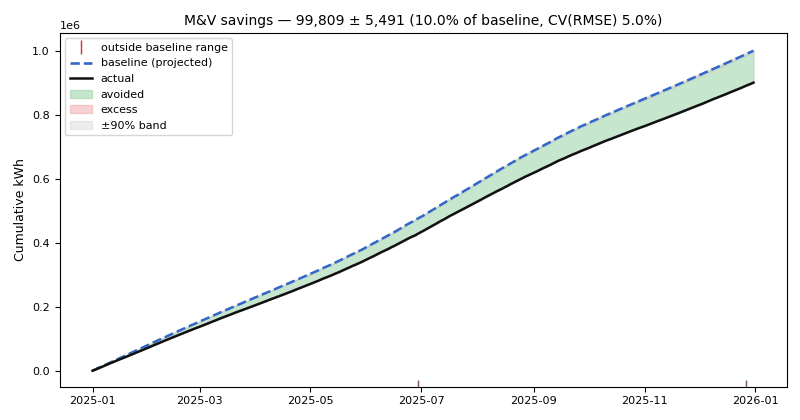
Synthetic data: charts.savings_chart for a 10 % saving: the baseline projected onto the reporting year's weather, the actual energy, and the G14 uncertainty band on the running total.
If the reporting weather lies far outside the baseline's, res.savings.declined is True and the
savings fields are None — see Extrapolation.
Two uncertainty kernels, and why
Which kernel applies depends on whether the savings difference contains measured energy:
measured − projected(Option C avoided energy, Option B isolation) carries the reporting period's own residual noise, which averages down over themreporting points. This is the G14 Annex-B form above.projected − projected(normalized annual savings, Option D) contains no measured energy at all — only parameter error, shared by every projected period. Its band is therefore independent of how many periods you normalize onto, and usesCV·√(p/n), the OLS average leverage.
The two have deliberately different provenance: the measured kernel is the published G14 expression,
constant and all; the projected one is textbook regression theory, cited as such rather than
borrowing G14's empirical 1.26 for a case it was never derived for.
Serial correlation widens both, via n′. Daily whole-building residuals are routinely correlated,
so an unadjusted band is optimistic — daily_changepoint_savings estimates ρ from the baseline residuals
automatically. Strictly the reporting-period ρ is wanted, but those residuals contain the saving
itself, so the baseline fit's ρ is the standard substitution.
Acceptance thresholds — and where we differ from CalTRACK
- CAMBER uses ASHRAE Guideline 14 acceptance tiers for CV(RMSE)
(
stats.cv_rmse_max_for: ~15% monthly, ~30% hourly) and reports NMBE. The daily 30 % tier is CAMBER's interpolation, not a G14 value; a daily verdict means it meets CAMBER's daily tier. - CalTRACK is stricter and more prescriptive: it specifies data-sufficiency rules (coverage, minimum days), explicit model-selection criteria, and hard limits that eemeter enforces. CAMBER's own baselines leave those policy choices to the caller, so a change-point or pooled-TOWT fit is not CalTRACK-compliant. Use the thresholds and the FSU to judge whether such a result is reportable. When compliance is required, use the CalTRACK 2.0 methods (0.105), which apply CalTRACK's data rules themselves.
Extrapolation: coverage, caveats and declining
A baseline is a regression over the conditions it was fitted on. Projected onto a reporting period
it never saw — a spring baseline applied to a summer — its slopes run past the data, and the
avoided energy and FSU describe a model nothing supports. IPMVP and ASHRAE Guideline 14 both expect
the baseline to cover the reporting conditions, or the extrapolation to be disclosed and bounded;
neither is quoted for the numbers below, and CalTRACK prescribes no extrapolation test. Every
threshold here is a CAMBER policy choice, set on mandv.coverage.ExtrapolationPolicy.
Every savings path — avoided_energy_savings, daily_changepoint_savings, towt_savings_hourly,
isolation_savings, normalized_savings, isolation_normalized_savings and the savings chart —
grades the baseline's coverage of the reporting drivers and acts on the tier:
| Tier | When (defaults) | What happens |
|---|---|---|
in_range |
≤ 5% of points and ≤ 5% of baseline-projected energy outside the support, and nothing more than 10% of the fitted range beyond it | Numbers exactly as before; coverage attached |
moderate |
anything short of severe | Caveat with the shares, the support and fitted ranges and the furthest distance; FSU widened by k (linear models) |
severe |
≥ 25% of points or energy outside, or > 50% of the fitted range beyond it, or a baseline driver that never varied while the reporting one does | Declined: avoided_energy, baseline_projected, savings_pct, fractional_uncertainty, abs_uncertainty → None; reporting_actual stays; declined_reason says why |
not_evaluated |
the model carries no fit range (a duck-typed or constant model), or no finite reporting rows | Numbers unchanged; a caveat says coverage was not checked |
Support. At fit time each model records its finite baseline drivers (one private fit record per
model). The support band is the 1st–99th percentile order statistics (support_quantile), so one
freak day does not stretch the range a whole season is judged against; points within 5% of the
band's width (edge_tolerance) count as covered. Shares are counted against the band, distance
beyond the hard [min, max] range as a fraction of its width. Both sides count, including a flat
segment of a change-point model — outside the data is outside the data, even where the model's
arithmetic happens to be benign.
Widening a moderate extrapolation. For linear-in-parameters baselines (change-point, degree-day,
Option-B driver models), with A = pinv(X′X) of the baseline design, s the sum of the reporting
design rows and s_c the same with each driver clamped into the support band:
- measured kernel (avoided energy):
k = √((m + s′As) / (m + s_c′As_c)) - projected kernel (normalized savings):
k = √(s′As / s_c′As_c)
and the reported FSU is FSU × max(1, k), with k recorded as fsu_extrapolation_factor. It is
the variance of the projected total at the actual drivers relative to drivers kept inside the
support — so it is conditional on the fitted change points (treated as known), it equals 1 where
the extrapolated points sit on a flat segment, and it tracks the mean design row: a few
extrapolated points in an otherwise central period barely move it, and the measured-noise term m
usually dominates it for avoided energy. It widens for parameter variance only; it cannot bound the
bias of a wrong functional form beyond the data, which is why severe extrapolation declines
rather than widens.
Several drivers. Each column is checked, and so is leverage: a reporting row with
h = x A x′ above the largest baseline leverage lies outside the joint region the data spans even
when every column is individually in range — hidden extrapolation (Montgomery, Peck & Vining,
Introduction to Linear Regression Analysis). A row outside on either test is outside.
TOWT (hourly). The unit is occupancy mode × temperature cell (below the fitted range, each of
the model's temperature segments, above it). A reporting hour is unsupported when its cell holds
fewer than 20 baseline hours (min_cell_obs) or lies beyond its mode's fitted range; distances
are per mode. Hour-of-week × temperature sparsity is reported in coverage["info"] for information
and never changes the tier. TOWT clips its temperature basis at the breakpoints, so it holds its
response flat beyond the fitted range (with fixed knots it continues its outer slopes
instead): the error there is bias, not parameter variance, so TOWT is flagged but its FSU is never
widened. A reporting hour in an hour-of-week bin the baseline never saw is unsupported whatever
its temperature, counted in coverage["info"]["n_unseen_tow_bin"] with a caveat; before 0.105 it
was silently graded as an unoccupied hour. By default TOWTModel.predict still raises on such
hours; unseen="fallback" predicts them from neighbouring bins
(see TOWT options), and they stay unsupported here.
The daily change-point path (daily_changepoint_savings) also caveats a baseline shorter than
365 days, which cannot span a weather year.
Normalized savings grade both models against the normal year (coverage_baseline,
coverage_reporting); a TMY colder than the reporting model's fit declines. Categorical models
treat a reporting category the baseline never fitted as unsupported (bind a period with
CategoricalModel.at(cat)); rows without a finite projection are counted (coverage["n_used"] vs
["n_report"]) rather than dropped silently.
Migration. Severe extrapolation declines by default, so the savings fields are float | None.
To keep computing it (with a widened band and a caveat starting "SEVERE extrapolation — not a
defensible saving"), opt out:
from camber.mandv.caltrack import daily_changepoint_savings
from camber.mandv.coverage import ExtrapolationPolicy

res = daily_changepoint_savings(
    baseline_energy,
    baseline_temp,
    reporting_energy,
    reporting_temp,
    extrapolation=ExtrapolationPolicy(decline=False),
)
Config runs. A config mv entry (see CLI.md) that names a reporting_period
emits one mv_savings finding per meter alongside its mv_baseline:
{"class": "CHILLEDWATER_METER", "role": "energy_rate",
 "period": ["2016-01-01", "2016-06-30"], "reporting_period": ["2016-09-15", "2016-11-30"],
 "extrapolation": {"decline_share": 0.30}}
Its metrics carry avoided_energy, savings_pct, fsu, fsu_extrapolation_factor and the
coverage (coverage_tier, share_points_outside, share_energy_outside, max_beyond_rel); the
baseline finding records the OAT support it was judged against (oat_fit_min, oat_fit_max,
oat_support_lo, oat_support_hi) and its residual rho, now estimated because the daily index
is passed to the fit statistics. A severe extrapolation — a winter baseline against a summer — is
an info finding with metrics["declined"] true, a declined_reason and a caveat, never a number.
extrapolation takes the ExtrapolationPolicy fields; an unknown key is an error.
assess_coverage(model, drivers) is direction-agnostic: it grades any fitted model against any
driver set, so the same call checks a reporting model projected back onto baseline conditions.
Model validity: coefficient p-values and the SEP verdict
stats.regression_tests(X, y, names=...) returns coefficient standard errors, t statistics and
two-sided p-values, the overall F-test p-value, adjusted R² and — given a time_index — the
residuals' lag-1 ρ and ρ-adjusted p-values (variance × κ, degrees of freedom n′ − p).
model_regression_tests(model, drivers, y) does the same for a fitted change-point, degree-day
or driver model. The t and F tails are computed in the standard library, through a regularized
incomplete beta evaluated by its continued fraction (DLMF 8.17.22); they are checked against
closed forms and the NIST StRD Norris certified regression.
Change points. A change point is grid-searched, not solved by least squares. It counts as a
parameter (the F-test is F(p − 1, n − p) with the change point in p, as FitStats does), but
the slope p-values are conditional on it: CAMBER treats change points as fixed, the G14
convention as described by BPA/SBW, Uncertainty Approaches and Analyses for Regression Models
and ECAM (2017) §2.3.1. The search makes those p-values optimistic, and every result says so
(conditional_on_change_points, plus a caveat).
stats.sep_validity(tests, signs=...) applies the DOE SEP 50001 M&V Protocol, 2019 Edition 2,
§6.4.1 (identical in the 2012 SEP M&V Protocol for Industry, §3.4.5):
- the overall F-test has p < 0.10;
- every relevant variable has p < 0.20, and at least one has p < 0.10;
- R² ≥ 0.50;
- the coefficients are consistent with a logical understanding of the process.
Relevant variables are the slopes — never the intercept or a change point. logical_signs(model)
supplies the signs physics fixes (a heating or cooling arm slopes upward away from its change
point); without signs the sign test is skipped, with a caveat. SEP's tests assume independent
residuals, so the verdict is reported as written (sep_valid, reproducible against the DOE EnPI
tool) and ρ-adjusted (sep_valid_rho_adjusted), with a caveat when they disagree.
This is a separate verdict from FitStats.accept, the G14-style gate (CV(RMSE), NMBE, R²)
that governs savings claims — which is unchanged.
from camber.mandv.models import fit_model
from camber.mandv.stats import logical_signs, model_regression_tests, sep_validity

m = fit_model(T, y, "3PC", time_index=days)
v = sep_validity(model_regression_tests(m, T, y, time_index=days), signs=logical_signs(m))
v.sep_valid, v.sep_valid_rho_adjusted, v.failures
Backcast savings
methods.backcast_savings is the SEP backcast (SEP 2019 Ed. 2 §6.2.2, Eq 9): a model fitted
on the reporting period, projected back onto the baseline period's conditions and subtracted
from measured baseline energy, S = O_b − P_r|b. SEP permits it when the baseline conditions fall
within the range of validity of the reporting-period model (SEP 2012 §3.6.3.1) — typically when
the baseline cannot support a valid model but the reporting period can.
- Coverage is the reporting model's support graded against the baseline drivers — the mirror image of a forecast. A mild-season baseline against a full-year reporting period is a severe forecast extrapolation but an in-range backcast.
- Uncertainty is the reporting model's: the G14 measured-savings kernel by default, with the
roles swapped (
mbaseline points,nreporting-fit points), or the exact kernel. - Labels. IPMVP 2012 calls a saving stated at baseline conditions normalized savings, and
the IPMVP Core Concepts review draft calls a backcast avoided energy; CAMBER claims neither
and labels the result
method="backcast",basis="baseline-period conditions".
from camber.mandv.methods import backcast_savings

res = backcast_savings(
    reporting_model, T_baseline, y_baseline, cv_rmse=st.cv_rmse, n_reporting=st.n, p_reporting=3
)
res.savings, res.savings_pct, res.abs_uncertainty, res.coverage["tier"]
The M&V flow: method, then adjustments, then result
A reported saving is built in three fixed steps, in this order, and each step is recorded on the result:
- Method. A declared SEP adjustment-model method (below) gives the routine saving:
forecast, backcast, standard conditions or chaining (or CAMBER's
sequential_chain), each aMethodResultwith its SEnPI, band and kernel.select_methodand"method": "auto"only propose one. - Adjustments. An explicit ledger of non-routine and static-factor adjustments restates the
method's baseline side (
apply_adjustments, below). For a chain each entry restates the one link whose dates hold it, and the SEnPI and saving are recombined by Eq 6 and Eq 11. - Result. The unadjusted and the adjusted saving are reported side by side, with the ledger, the waterfall and the combined band. Nothing is adjusted implicitly: a detected step is only a proposal until an analyst accepts it.
One validity setting (g14, sep or both; decision D1 on #21) governs the whole flow: G14
acceptance for the savings claim, SEP §6.4.1 model validity for the SEnPI, and, under sep or
both, SEP §5.3.2's evidence and approval on every adjustment. The ECM dates and the settle
window after each (EcmSchedule, 14 days by default) are declared once and shared by the
confounding guard, the detection proposals and the rebaselining policy
(below).
SEP methods: forecast, backcast, standard conditions and chaining
camber.mandv.methods implements the four adjustment-model methods of the DOE SEP 50001 M&V
Protocol, 2019 Edition 2, §6.2, with one result type, MethodResult. All of it is provisional.
Every result records its method, its basis and its uncertainty kernel.
- Forecast (§6.2.1),
forecast_savings. The saving isP_b|r − O_r(Eq 8) and the SEnPIO_r / P_b|r(Eq 5). Default kernel: G14. - Backcast (§6.2.2),
backcast_savings. The saving isO_b − P_r|b(Eq 9) and the SEnPIP_r|b / O_b(Eq 5). Default kernel: G14. - Standard conditions (§6.2.3),
standard_conditions_savings. The saving isP_b|s − P_r|s(Eq 10) and the SEnPIP_r|s / P_b|s(Eq 5). Default kernel: exact. - Chaining (§6.2.4),
chained_savings. The saving is(O_b − P_i|b) + (P_i|r − O_r)(Eq 11) and the SEnPI(P_i|b / O_b)·(O_r / P_i|r)(Eq 6). Kernel: exact.
O is measured energy and P_x|y the model of period x applied to the conditions of period
y. savings_pct is the SEP improvement as a fraction, 1 − SEnPI (Eq 7 ÷ 100). sep_terms
holds the SEP quantities for aggregation.
Chaining is SEP's method, exactly. It uses one intermediate period "of the same length of,
and ... in between the baseline and reporting periods" (§6.2.4). Its model is backcast onto the
baseline and forecast onto the reporting period, and it must cover both (SEP 2012 §3.6.5).
chained_savings checks the period rule and raises ValueError when it fails. CAMBER allows one
day's difference in length, for a leap year; the Protocol states no tolerance. A severe
extrapolation on either side declines the result. The chained SEnPI is a product (Eq 6), and
the chained saving a sum (Eq 11). EnPI V5 adds cumulative improvement percentages for
pre-model years; that is bookkeeping, and CAMBER follows the Protocol instead.
sequential_chain is a CAMBER extension, not SEP. It chains any number of consecutive
MethodResult links, for example year-over-year forecasts against rebaselined models. The SEnPI
is the product of the links and the saving their sum. Every result carries a caveat saying the
chain is not an SEP method, and it has no sep_terms, so it cannot be aggregated into an SEP
SEnPI.
Uncertainty
SEP says nothing about uncertainty. These bands are CAMBER's. The kernel defaults follow decision
D7 on #21: the G14 kernel for single-model results and the exact kernel for multi-model results.
With Σ = κ s² A the model's parameter covariance and g the sum of the design rows:
Forecast / backcast:  as avoided_energy_savings / backcast_savings (G14 or exact)
Standard conditions:  Var S = V_param,b(s) + V_param,r(s)                     (IPMVP 2012 B-19)
                      Var ln SEnPI = V_param,r/P_r|s² + V_param,b/P_b|s²      (delta method)
SEP chain:            Var S = (g_r − g_b)′ Σ_i (g_r − g_b) + V_noise,i(b) + V_noise,i(r)
                      Var ln SEnPI ≈ T_b/P_i|b² + T_r/P_i|r² − 2 g_b′ Σ_i g_r /(P_i|b · P_i|r)
                      (T = V_param + V_noise; the noise part taken relative to O_b, O_r)
Sequential chain:     Var S = Σ_k Var S_k (B-19);  Var ln SEnPI = Σ_k Var ln EnPI_k (B-20)
Single-model SEnPI:   band(SEnPI) = SEnPI · band(S) / denominator            (delta method)
Both projections of the SEP chain share one β̂_i, and their parameter errors enter with opposite
signs. The independence form therefore over-states the chain's uncertainty whenever
g_b′ Σ g_r > 0, which is typical, because the intercept column dominates. So the chain uses the
exact covariance form and reports the independence variance beside it (uncertainty_terms). The
intermediate model's κ s² stands in for the noise of both measured periods. The chain always
uses the exact kernel (kernel="g14" raises), because the G14 expression has no covariance term.
Monte Carlo. The test used synthetic 3P-cooling data with AR(1) residuals, ρ estimated from the intermediate fit, and 600 seeded runs per ρ. The baseline and reporting climates differed, and the intermediate year spanned both. The nominal 90% chain band covered the true saving in 90–92% of runs at ρ = 0, 0.4 and 0.8, and the SEnPI band did the same. At ρ = 0 the predicted variance matched the empirical one to within 15%. The independence form's variance was about 1.5× the exact one. CI gates coverage at 85–95%. As elsewhere, these results are conditional on the fitted change points.
The sequential chain's B-19/B-20 combination assumes the links are independent. That holds only approximately. A link whose model was fitted on a period that another link measures shares that period's noise, and the result's caveat says so.
The SEP range rule (secondary)
SEP §6.4.2.1 requires the mean of each relevant variable over the application period to fall
within the fitted range, or within three standard deviations of the fit mean.
sep.sep_range_check applies it, and every method result reports the outcome as
sep_range_valid, with details in sep_range. This verdict is secondary (decision D2). The
primary guard stays the per-point coverage tier: a mild mean can hide hot extremes on a
change-point slope, and the mean rule passes them. The standard deviation is the sample one
(ddof = 1), a CAMBER choice.
Choosing a method, and the method-shopping guard
select_method(frame, baseline=..., reporting=...) follows SEP's order:
- forecast, if the baseline model is SEP-valid and covers the reporting period (per-point coverage not severe, and SEP's mean rule holds);
- backcast, if the reporting model is valid and covers the baseline;
- chaining, through the best-ranked valid intermediate window of the baseline's length lying between the two periods whose model covers both;
- standard conditions, if both models are valid and cover the supplied conditions;
- otherwise, decline (SEP 2012 §3.6.6).
In every period the candidate models are ranked by SEP validity, then adjusted R², as the DOE EnPI tool does.
It only proposes. Valid methods can disagree widely. Chen & Therkelsen (LBNL-2001209, 2019)
found all four SEP methods valid on one facility, with SEnPI ranging from 0.93 to 1.00. So the
proposal has no headline figure. Its sensitivity table lists every valid method's saving,
SEnPI and band side by side. A reported saving needs a declared method: in a config, set
mv[].method. "method": "auto" gives an mv_method_proposal finding, never an mv_savings
one. When no method is declared the run keeps the SEP default, forecast, and the finding says the
method was not declared. Freezing the declared method with a versioned baseline comes in a later
phase of #21.
{"class": "CHILLEDWATER_METER", "role": "energy_rate",
 "period": ["2016-01-01", "2016-12-31"], "reporting_period": ["2018-01-01", "2018-12-31"],
 "method": "chaining", "intermediate_period": ["2017-01-01", "2017-12-31"], "kernel": "exact"}
method takes forecast, backcast, chaining (with intermediate_period),
standard_conditions (with normal_year, a list of daily mean temperatures) or auto. kernel
takes g14 or exact, and defaults per D7.
SEP arithmetic and primary energy (mandv.sep)
senpi(Eq 5),chained_senpi(Eq 6),improvement_pct(Eq 7) andtop_down_savings(Eq 8–11). Golden tests reproduce the SEP 2019 Guidance's Eagleston ratio example (7.38%) and Ashton forecast (13.53%, which the Guidance rounds to 14%). The Guidance's range-check example is not used, because its arithmetic is wrong (see #21).bottom_up_reconciliation(Eq 12):RF = ESP_BU / ESP_TD. Below 0.80, the verified improvement is the top-down one times RF. RF is never used to scale an improvement up.primary_energy(Eq 1) andANNEX_B_MULTIPLIERS: only rows transcribed from the Protocol's own Annex B (Tables 4A/4B). Examples are grid electricity 3.0, solar, wind and geothermal electricity 1.0, fired-boiler steam or hot water 1.33, fired absorption chilled water 1.25, engine-driven chilled water 0.83, electric chilled water 0.72, compressed air 3.0, and the fuels 1.0. A user table overrides or extends it. A caveat notes that SEP requires Verification Body approval for site-specific multipliers. A negative net consumption counts as zero (§5.1.2).aggregate_energy_types: oneMethodResultper energy type, all with the same method (§6.2). Each is converted to primary energy and summed (§6.3.2) before Eq 5–11 are applied. The savings bands combine in quadrature (B-19).- Delivered physical units (0.92, #69). Both functions take
units=(every type's delivered unit, such as kWh, therm or Mcf),heat_content=/enthalpy=for gas volumes and steam, andenergy_unit=(kWh or kBtu). Each type is converted to energy first and the Annex B multiplier is applied after. A missing, unknown or ambiguous unit, or a volume without its heat content, is refused. See UNITS.md.
The exact uncertainty kernel
Every savings function takes kernel="g14" (the default, as documented above) or
kernel="exact". For a model fitted on n points with p parameters, residual variance s²,
lag-1 residual autocorrelation ρ (κ = (1+ρ)/(1−ρ)) and A = (X′X)⁻¹, applied to m rows whose
design rows sum to g:
V_param = κ s² g′Ag        (parameter error of the projected total)
V_noise = κ s² m           (noise of m measured points)
avoided energy / backcast:  band = t(n − p) · √(V_param + V_noise)
normalized:                 band = t(min(n − p)) · √(V_param,b + V_param,r)
This is the textbook OLS prediction variance of a sum (BPA/SBW 2017 §3.3); κ inflates both terms,
the conservative choice (CAMBER decision D3 on #21). It carries the leverage of the application
conditions itself — a projection far from the fitted mean has a large g′Ag — so a band
computed with it is never widened again for extrapolation: fsu_extrapolation_factor is 1.0.
Projected onto its own baseline rows it reduces to CV/√n of the in-sample total (for a model
with an intercept g′Ag = 1′H1 = n), which the conservative CV·√(p/n) projected kernel bounds
from above. It needs a CAMBER-fitted model, whose fit record holds (X′X)⁻¹, s², n, p and —
when fitted with a time_index — ρ.
Coverage. In a seeded Monte Carlo — daily change-point data, AR(1) residuals, ρ estimated from the baseline fit, 1,000 runs per ρ — the exact kernel's nominal 90% band covered the true saving 90.2%, 90.0% and 86.6% of the time at ρ = 0, 0.4 and 0.8; CI gates it to 85–95%. The G14 kernel covered 86.3%, 85.5% and 82.5% on the same data. Both are conditional on the fitted change points; the published evidence is that G14 bands under-cover real buildings (Touzani, Granderson, Jump & Rebello, Energy & Buildings 193:216–225, 2019: about 71% at nominal 95% for daily models), which synthetic data cannot reproduce.
G14 stays the default, with a caveat on every result (a maintainer decision on #21). The
Monte Carlo index in tests/test_mandv_mc_coverage.py (a year of daily 3PC data per period, AR(1)
residuals at ρ = 0, 0.4 and 0.8, ρ estimated, 400–600 runs per cell) measures every savings path
with a correct model:
| Path | G14 kernel at nominal 90% | Exact kernel at nominal 90% |
|---|---|---|
| Forecast (avoided energy) | 82–88% (under-covers) | 87–91% |
| Backcast | 82–88% (under-covers) | 87–91% |
| Standard conditions | 99–100% (conservative) | 87–91% |
G14's 1.26·√(m(1 + 2/n)) factor falls short of the √(2m) that parameter error plus reporting
noise need when m = n; CAMBER's projected CV·√(p/n) kernel for standard conditions errs the
other way. So every result computed with kernel="g14" — a SavingsResult, a forecast, backcast
or standard-conditions MethodResult (and so each link of a sequential chain), and an
AdjustedResult whose band is G14's — carries a caveat saying which way its band is miscalibrated
and that kernel="exact" is on target: switch to kernel="exact" for calibrated bands. The
caveat is text only; no band, saving or benchmark metric changes. The default will be revisited at
1.0.
Unverified. The ASHRAE text was not consulted. A BPA reproduction of the G14 kernel writes
(1 + 2/n′) where CAMBER writes (1 + 2/n); which is G14's is unverified, and CAMBER keeps
its current form until it can be checked against Reddy & Claridge (2000). The G14 formula for
normalized savings is likewise unverified; normalized_savings combines the two models in
quadrature (IPMVP 2012 Appendix B-5, B-19; BPA Meter-Based Energy Modeling Protocol 2024 §5.9)
at Student's t on the smaller fit's degrees of freedom, with each model's own ρ.
Non-routine events (NRE)
Shutdowns, occupancy changes or meter outages are by definition what the weather model can't explain, and they skew a baseline. CAMBER has three detectors, all on the residuals of a daily change-point weather model:
detect_non_routine— point-wise: days whose residual is a robust (MAD) outlier.daily_changepoint_savings(..., exclude_non_routine=True)drops those baseline days and refits, so a one-off shutdown doesn't distort the savings.detect_step_change— one sustained level shift, by the largest two-sample statistic over all splits. Passautocorrelation=True(recommended): it divides the statistic by√κ,κ = (1+ρ)/(1−ρ). Daily whole-building residuals routinely have ρ ≈ 0.6 (the BDG2 median), which inflates the uncorrected statistic about 2×; on synthetic step-free data at ρ = 0.8 the uncorrected default fires on nearly every run. The default is left unchanged so existing results do not move. Its residuals come from a model fitted through the step, so the ρ it estimates is inflated — conservative.-
detect_step_changes— several steps at once:- fit the weather baseline;
- segment the residuals with PELT (Killick, Fearnhead & Eckley 2012) using a Gaussian
mean-change cost whose variance is inflated for serial correlation,
σ²κ— the variance of a segment mean under AR(1) residuals — and an mBIC-style penalty of3 ln nper step, with segments at leastmin_segment_days=28long and at mostmax_steps; - refit the weather model with one level indicator per segment, so a step is not absorbed
into the temperature slope, and re-estimate
σandρfrom that fit; - repeat until the step set is stable (at most three refinement rounds).
The first round segments on a first-difference noise scale, because a step inflates both the fit's residual variance and its ρ; the steps reported always come from a later round. Each step carries its size (post − pre level) and a ρ-inflated standard error. This is the approach of Touzani, Ravache, Crowe & Granderson, Energy & Buildings 185:123–136 (2019), applied to the model residuals. On synthetic AR(1) sites it placed two planted steps to the day and flagged none of 50 step-free runs at ρ = 0, 0.4 and 0.8.
changedetect.detect_level_shifts(greedy binary segmentation, independent-residual statistic) finds the same clear steps but also spurious ones: it fired on most step-free runs at ρ = 0.8.
Detection only reports. adjustments.propose_adjustments turns detected steps into proposed
adjustments, which must be accepted explicitly before they change a saving (next section).
A step against a frozen baseline is a rebaselining trigger
(T1, below).
Non-routine and static-factor adjustments
IPMVP writes savings as (Baseline − Reporting) ± Routine ± Non-routine (IPMVP 2012 Vol. I §4.5.3,
Eq 1a). The routine part is the weather model; the non-routine part restates the baseline for what
the model cannot see — a change in a static factor (floor area, occupancy type, shifts,
equipment) or a non-routine event (a shutdown, a new load). SEP requires the numeric inputs of
such an adjustment to be observed, measured or metered, the method and rationale recorded, and
prior Verification Body approval (SEP 50001 M&V Protocol 2019 Ed. 2 §5.3.2).
camber.mandv.adjustments (provisional) keeps every adjustment as an explicit ledger entry —
a NonRoutineAdjustment or a StaticFactorAdjustment — and never adjusts implicitly.
apply_adjustments(result, ledger, ...) takes a finished saving (a SavingsResult or any
MethodResult), restates its baseline side entry by entry and returns an AdjustedResult:
the adjusted saving, SEnPI and bands, the resolved ledger (each entry with its amount, standard
error, materiality flag and, in a chain, its link) and the waterfall from baseline to reporting
energy. An empty ledger reproduces the method's own saving, SEnPI and bands.
Sign convention. An amount is the change to the baseline side, in the result's energy units over the rows it summed: a new load in the reporting period is positive, a partial shutdown negative.
Each method's baseline side.
| Method | Baseline side restated | How an entry is dated |
|---|---|---|
| Forecast | the baseline projection onto the reporting rows | against the reporting rows it summed (index=) |
| Backcast | the measured baseline energy | by its share of the reporting model's fit rows (reporting_index=), times the rows summed; an indicator dated inside the baseline rows is removed from O_b |
| Standard conditions | the baseline model's projection at standard conditions | as for a backcast; the rows are the (undated) standard conditions, so exclude is refused, and a baseline-period indicator replaces that projection by its augmented fit with the event absent |
| SEP chain | link 1: the measured baseline; link 2: the intermediate model's forecast | each entry belongs to the one link whose dates hold it: link 1 runs from the baseline start to the day before the intermediate period, link 2 from the day after it to the reporting end |
| Sequential chain | each link's own baseline side | a link's dates are its reporting rows (forecast link) or its model's fit rows (backcast or standard-conditions link), from links= |
In a chain an entry restates only its own link; the chained SEnPI is re-multiplied (Eq 6) and the
saving re-summed (Eq 11). The SEP chain carries its shared-model covariance through: with c₂ the
multiplier a proportional factor applied to link 2's projection,
Var S = Σ_k (Var B′_k + Var R′_k) − 2 c₂ g_b′Σ_i g_r, and the SEnPI's delta-method variance loses
2 c₂ g_b′Σ_i g_r / (P_i|b · B′_2). A sequential chain combines its adjusted links as independent
(B-19 / B-20). Three things are refused inside a chain, each with the reason: an entry dated in the
SEP chain's intermediate period (both links share that model, so one link cannot be restated
alone), an exclude entry (drop the rows from the chain's inputs and recompute it instead; the
two are the same thing), and a baseline-period indicator refit (refit that link's model and
recompute). For standard conditions the band is split between the two models by their exact-kernel
terms (with the G14 kernel, by assuming equal relative uncertainty, with a caveat).
| Method | What it is | Uncertainty |
|---|---|---|
indicator |
The event's effect per row, as the coefficient of an indicator in the weather regression (BPA Regression for M&V Reference Guide 2024 §3.1.7; BPA/SBW Potential Analytics for NRAs 2018 §3.1), by estimate_nre_indicator. Each indicator adds one to p. |
fit_period="baseline": the indicator is fitted inside the baseline model, whose augmented form replaces the projection (indicator 1 on the rows the event covers, 0 elsewhere); the band is g′Σg + κs²m of the augmented fit with the joint Σ = κs²(X′X)⁻¹. fit_period="reporting": a mini pre/post fit inside the reporting period, independent of the baseline, so quadrature — except on a backcast, where a fit over the reporting model's own rows is that model refitted with the indicator: it replaces the reporting projection the same way (joint Σ, p + 1). |
engineering |
An estimate and its standard error; evidence is required (SEP §5.3.2). |
Quadrature (IPMVP 2012 App. B-5, B-19). |
exclude |
Drop the event's span from both sides — SEP §6.5 treats an anomaly as its own operating mode. | The G14 band rescales as the kernel does (∝ P²/m); the exact kernel is recomputed on the kept rows. A caveat gives the rows dropped. |
submeter |
The effect measured at a sub-meter, the Option B path IPMVP 2012 §8.2 prefers; nra_from_isolation builds one from an IsolationSavings. |
Quadrature. |
Static factors. proportional scales the affected share f of the baseline by the factor's
ratio r = s_r/s_b: B′ = (1 + (r − 1)f)·B. There is no default share (CAMBER decision D8
on #21): affected_share must be stated. The baseline side's standard error scales with the
multiplier — correlated with the projection, not added in quadrature — plus the terms of the
optional standard errors of r and f. A factor that starts mid-period scales only the rows
after it (weighted by projected energy when the model and drivers are given). engineering is an
estimate with a standard error and evidence. A driver that varies continuously — occupancy,
production, hours — is a relevant variable, not a static factor (SEP §5.4): model it with a
change-point + driver model (below) instead.
The combined band is at Student's t on the smallest contributing degrees of freedom. The saving's
own band is converted back to a standard error at its confidence and degrees of freedom (the
large-sample t when a SavingsResult does not record them, which slightly overstates it).
A backcast with a reporting-period indicator refits the reporting model (a maintainer decision
on #21). A backcast's reporting side is the reporting model, fitted through the event: the event
inflates that fit's s² and ρ, and its band came out about 20× the error's standard deviation
in Monte Carlo (100% coverage at nominal 90%). When the indicator was fitted on the reporting
model's own rows, its fit is that model refitted with the indicator, so apply_adjustments
projects it onto the baseline rows (event absent there, unless the rows hold it) with the joint
Σ and p + 1, as a baseline-period indicator does on the other side. The result is on the exact
kernel. In seeded Monte Carlo (a year of daily 3PC data per side, a new load from day 200 of the
reporting year, 600 runs per cell) it covers 86% / 88% / 86% at ρ = 0 / 0.4 / 0.8, unbiased,
gated at [0.85, 0.95]; like every indicator band it is conditional on the re-searched change
points. It needs drivers= for the baseline rows; without them, inside a chain, with a second
reporting-period indicator, or when the indicator was fitted on another window than
reporting_index=, the entry adds in quadrature to the unadjusted band and a caveat says the
band is conservative.
Guards.
- Confounding. A meter-derived NRA (indicator, exclude) whose start or end is within
settle_days(default 14) of an ECM date raisesConfoundedAdjustment: the meter cannot tell the event from the measure. IPMVP 2012 §8.2 goes further — "Option C cannot be used to determine savings when the facility's energy meter is also used to quantify the impact of changes to static factors" — so every meter-derived entry carries that caveat (CAMBER decision D6 on #21 allows it with the guard). - SEP. Under
validity="sep"(or"both") every entry needsevidenceandapproved_by. - Proposals.
propose_adjustments(detect_step_changes(...))returns onestatus="proposed"indicator entry per step, with a materiality flag and a caveat when it falls near an ECM date.apply_adjustmentsrefuses a proposed entry;entry.accept(approved_by=...)accepts it. Better: re-estimate the declared window withestimate_nre_indicator— the detector's step size comes from a fit over the whole series.
Materiality is CAMBER's rule, by analogy with IPMVP 2012 App. B-1.2 (savings should exceed
twice their standard error): an event is flagged when |effect| ≥ max(threshold, 2·SE)
(is_material; materiality_threshold in energy units over the period).
from camber.mandv.adjustments import (
    NonRoutineAdjustment,
    StaticFactorAdjustment,
    apply_adjustments,
    estimate_nre_indicator,
)

nra = estimate_nre_indicator(
    T_report,
    y_report,
    report_index,
    start="2024-06-01",
    fit_period="reporting",
    model=baseline,
    reason="tenant moved out",
)
wing = StaticFactorAdjustment(
    factor="floor area",
    method="proportional",
    start="2024-01-01",
    reason="new wing",
    baseline_value=10_000,
    reporting_value=12_000,
    affected_share=0.5,
)
adj = apply_adjustments(
    savings,
    [nra, wing],
    index=report_index,
    drivers=T_report,
    measured=y_report,
    model=baseline,
    ecm_dates=["2024-03-01"],
)
adj.savings, adj.abs_uncertainty, adj.ledger, adj.waterfall
camber.charts.adjustment_waterfall(adj) draws the waterfall: the baseline projection (and, given
baseline_actual=, the measured baseline and the routine adjustment), each entry in the order it
was applied, the adjusted baseline, the saving with its band, and the reporting energy; material
entries are starred.
Coverage. In seeded Monte Carlo runs — daily 3PC data with AR(1) residuals, the change point re-searched with the indicator in the design, ρ estimated, 600 runs per case — the indicator's nominal 90% band covered the planted effect 91.5%, 90.0% and 84.8% of the time at ρ = 0, 0.4 and 0.8 for a mini pre/post fit in the reporting period, and 90.0%, 86.3% and 85.0% for a closure inside the baseline. CI gates these at 85–95%, and at 80–95% for ρ = 0.8, where the lag-1 estimate of a one-year fit is biased low and κ under-corrects. The adjusted saving after a baseline-period indicator refit covered 86–89%, 84–86% and 83% at ρ = 0, 0.4 and 0.8 (400 runs, a winter and a summer closure) — two to three points below the plain exact kernel, the cost of re-searching the change point on less data. All of these are conditional on the change points. The adjusted SEP chain — a new 30-per-day load planted in the reporting year, estimated by a reporting-period indicator on link 2, the chain's shared-model covariance carried through — covered the true saving 89.5% of 200 seeded runs (the CI gate, 85–95%) and 91.3% of 600; the unadjusted chain, biased by the load, covered it in none.
A caution. An indicator fitted over a short window soaks up whatever the weather model misses: on a synthetic autumn window with a smooth, slightly mis-specified cooling response, an indicator at an arbitrary date came out "material". Prefer a full-year fit window, and treat an indicator that is not backed by a logged event as a question, not an adjustment.
Config runs. An mv entry with a reporting_period may carry an adjustments ledger — the
dict form of the entries ("kind": "nra" or "static", plus the dataclass fields). It is applied
after the declared method, to that method's result. An indicator entry carries no numbers: it
is estimated per meter on the baseline days ("fit_period": "baseline") or the reporting days
("reporting"), by default the period its start falls in, against the model the method projects
(the baseline model for a forecast, the reporting model for a backcast, the intermediate model for
a chain). ecm_dates, settle_days, validity and materiality_threshold drive the guards. The
mv_savings finding then carries adjusted_savings, adjusted_savings_pct,
adjusted_abs_uncertainty, adjusted_baseline, adjusted_enpi (and, for a chain,
adjusted_links), the resolved adjustments and the waterfall; a refused ledger (confounded,
missing SEP evidence, or an entry a chain cannot take) records adjustments_refused and a caveat
and leaves the unadjusted saving standing. With "method": "auto" the ledger does not change the
proposal; each sensitivity row gains the adjusted_* figures beside its unadjusted ones. A malformed entry (for example a proportional factor without
affected_share) is a config error.
{"class": "CHILLEDWATER_METER", "role": "energy_rate",
 "period": ["2016-01-01", "2016-12-31"], "reporting_period": ["2017-01-01", "2017-12-31"],
 "method": "forecast", "validity": "g14", "ecm_dates": ["2017-03-01"], "settle_days": 14,
 "adjustments": [
   {"kind": "nra", "method": "indicator", "start": "2017-05-01", "reason": "server migration",
    "evidence": "work order 123"},
   {"kind": "static", "method": "proportional", "factor": "floor area", "start": "2017-01-01",
    "reason": "new wing", "baseline_value": 10000, "reporting_value": 12000,
    "affected_share": 0.5}]}
Versioned baselines and rebaselining
A saving is only as good as the baseline it is measured against, and a baseline that moves
silently makes every past saving unanswerable. camber.mandv.rebaseline (provisional; issue #21
phase 21d) keeps each meter's M&V baselines frozen and versioned, and decides only what to
propose when one stops holding. CAMBER never rebaselines automatically.
The versioned store
MVBaselineStore wraps the drift BaselineStore (identity sha1(facility_id, equip, kind),
kind = "mv_<role>", so a new model form stays on the same record). Version 1 is frozen
(freeze_version, never overwriting one); a later version supersedes it only through the
attributed rebaseline, whose window must start after the previous one ends. Superseded versions
stay in the record's history: past reported savings depend on them. Inside a portfolio
workspace the file is state/<fid>/mv_baselines.json, with a "schema" field on disk;
outside one, name it with the config's top-level "mv_store".
Every version carries a provenance record (mv_provenance): the reason and the trigger ids
(T1:2018-02-01), accepted_by plus the OS user and host, the data window and a sha256 of
the fit frame (so a later re-ingest that changes the data under a frozen baseline is caught and
reported), the model's as_dict, its FitStats, RegressionTests and SEP verdict, the
declared method and kernel, the validity regime, the policy it was checked against, the
adjustment ledger, the CAMBER version and a content_sha256 (MVBaselineStore.verify). The
ledger is append-only and round-trips losslessly, indicator fits included
(IndicatorFit.from_dict). The declared method is frozen with the baseline: changing it later
is a rebaseline-class action (the method-shopping guard, above).
Triggers and outcomes
assess_triggers evaluates six triggers against a version (issue #21 §2.6):
| ID | Trigger | Outcome |
|---|---|---|
| T1 | A material step change the declared ECMs do not explain | indicator NRA, or a rebaseline when the level shift is at least major_step_frac (default 20%) of the baseline projection |
| T2 | A declared significant change (rebaseline.events) |
by its magnitude: static → engineering NRA, minor → indicator NRA, major → rebaseline |
| T3 | A tracked static factor changed beyond its tolerance (rebaseline.static_factors) |
static-factor NRA |
| T4 | The model fails the validity regime, or #20 grades the reporting period severe |
rebaseline |
| T5 | The achievement period exceeds 36 months (SEP 2019 Ed. 2 §4.2) | rebaseline |
| T6 | A new ECM, after the reporting period began, with 12 months of post-ECM data (BPA 2024 §3.1.8) | rebaseline (advisory: savings are not declined) |
Outcomes follow the BPA Regression for M&V Reference Guide (2024) taxonomy: static change →
engineering or sub-meter NRA; minor process change → indicator NRA; major process change →
rebaseline, then chain. The 20% line between minor and major is CAMBER's choice, not a
standard's. T1 segments the relative deviation of every day since the baseline ended from the
frozen projection, energy / projection − 1, by PELT with a ρ-inflated variance and a
3 ln n penalty (Touzani et al. 2019): a change that scales the load is one level shift whatever
the season. A step within settle_days of a declared ECM is the measure itself, and one the event
log already carries is T2. An accepted ledger entry dated within settle_days resolves an
NRA-class trigger; a later version resolves every trigger dated before its window. A trigger
dated inside an SEP chain's intermediate period can only be answered by a rebaseline or another
intermediate window: both links share that model.
The new-baseline window, or a decline
propose_rebaseline anchors the new window after the latest unresolved rebaseline-class trigger
and any later blocking trigger, so a new baseline never straddles a known step. The window is
the latest min_baseline_days (365) consecutive days that start at least settle_days after
it, overlap no ECM installation window (ECM date ± settle_days), miss at most
max_missing_frac (10%) of their days, fit a model valid under the entry's validity, and
cover the expected conditions (every driver value seen, at a #20 tier short of severe).
Otherwise the proposal is declined with the days still needed:
unresolved non-routine event on 2018-02-01 (T1:2018-02-01); rebaseline needs 105 more days
(a 365-day window starting 2018-02-15 or later, 14 settle days after it)
The run path is read-only
When a meter has a frozen version, camber run and camber mv run measure the reporting period
against the version in force (the latest whose window ended before the reporting period
starts), never refitting and never writing. Every MethodResult and AdjustedResult records
the baseline_version it used. The version's recorded ledger is applied with the config's.
Triggers become mv_trigger findings (warn when unresolved and blocking). An unresolved
blocking trigger cuts the saving at its date (partial, with a caveat), or declines it when it
precedes the reporting period. A later version cuts the saving where it takes over.
A chain across versions
camber mv report reports each version's segment (from the day after its window to the day
before the next version's trigger) as a forecast against that version, restated by its own
ledger. Between a trigger and the end of the next window nothing is reported. Two or more
segments combine through sequential_chain, a CAMBER extension (SEP chains through exactly
one intermediate period), with each link dated from the store (windows=) so a ledger entry can
be dated against a link without row indexes. The chained CUSUM (chained_cusum_plot) draws one
segment per version, continuing from the previous segment's last value (the EnPI V5 tool's
convention for chained model years), with the rebaseline triggers marked and the unreported gaps
shaded.
Configuration
{"class": "ELEC_METER", "role": "energy_rate", "period": ["2016-01-01", "2016-12-31"],
 "reporting_period": ["2017-01-15", "2019-12-31"], "method": "forecast", "validity": "g14",
 "ecm_dates": ["2017-01-01"], "settle_days": 14,
 "rebaseline": {"detect": true, "min_segment_days": 28, "materiality": 0.0,
                "major_step_frac": 0.20, "min_baseline_days": 365, "max_missing_frac": 0.10,
                "max_achievement_months": 36, "ecm_gap_days": 365,
                "events": [{"date": "2018-02-01", "description": "wing closed", "magnitude": "major"}],
                "static_factors": [{"factor": "floor_area", "baseline_value": 5000,
                                    "value": 6000, "date": "2018-06-01", "tolerance": 0.05}]}}
The settle window is mv[].settle_days, one value shared with the confounding guard. A
rebaseline.settle_days that differs from it is refused, not reconciled. Unknown keys are
errors.
A billing entry may add "bill_steps": "scan" (0.95), its own step test for trigger T1; see
Step changes on bills.
The verbs are in CLI.md. The real limits are worth stating: the bands are model-error only and under-cover in practice (Touzani et al. 2019). A meter whose daily energy follows occupancy more than weather (weekday/weekend) may never fit a valid daily change-point model. CAMBER then says so (T4, declined windows) rather than rebaselining onto an invalid model.
Daylight-saving days (provisional, 0.93)
CAMBER's series are naive wall-clock time, so a daylight-saving change leaves two marks on a daily M&V frame. The spring-forward day has 23 hours: its skipped hour holds no sample, and the day's energy was always summed over 23. The autumn fall-back day has 25, but its repeated hour fits in one naive stamp. The store's hourly resample averages that hour's two readings, and a trend export often keeps only the first, so the day came out with 24 hours of energy, one short.
When the site's zone is known, mandv.intervalfit.daily_energy_vs_temp(..., timezone=) counts a
sample in the repeated hour for both passes of the clock (repeated_hour_weights). The day then
sums 25 hours of energy, and its mean temperature weights that hour twice. The weight lands only
on the fall-back days, so every other day is bit for bit what it was. An export that kept both
readings under one stamp is averaged first, so both count. The zone comes from source.timezone,
or, for a store facility, from the zone the facility records, looked up as the read API's
/facilities does (0.100, #104): a timezone on its registry entry, the dataset block on the
entry (a per-site zone, as each BDG2 site records), the catalog entry's local_timezone (for
example cofactor-drammen, Europe/Oslo), then an open-fdd ingest's zone. Every daily mv path takes it: the plain run, each
declared method, the ledger and the versioned baselines of camber mv. A source with no zone
keeps the historical days.
Hourly frames (0.105, #158). mandv.intervalfit.hourly_energy_vs_temp used to sum duplicate
timestamps, so an export that kept both readings of the repeated hour counted that hour's energy
twice. It has no zone to tell which reading is which, so now:
- With
timezone=(also ontowt_savings_hourly), the samples are placed on their real instants (timegrid.localize's convention), and both real hours of the fall-back are kept, each with its own energy and temperature. A lone sample in the repeated hour (the store's hourly mean of the two passes) stands for both, asrepeated_hour_weightscounts it twice on the daily path. The fall-back day has 25 rows and the frame a tz-aware local index;houris the local clock hour. - Without a zone, duplicate timestamps are one hour. Energy and temperature are averaged per
stamp (
timegrid.regularize(dedupe="mean")), never summed, andattrs["n_duplicate_stamps"]counts them. Acamber.tsparse.TimezoneWarningsays to pass the zone;towt_savings_hourlyadds the count to its caveats.
A rate meter's step is now taken from the positive gaps only, so heavily duplicated stamps no longer give a zero step and zero energy. Hourly data without duplicates is unchanged.
On the COFACTOR import meters (hourly, stored on the Oslo clock) the fall-back days now match
the publisher's fixed-offset data exactly, where they were 3 to 5 % short. The spring-forward days
were already right. The same holds for a US series in America/Los_Angeles (the lbnl-b59
whole-building electricity, published in UTC).
Day coverage (0.105, #157)
A daily frame used to sum whatever samples a day held, so a day missing hours counted as a whole
day and read low. On a gappy meter that biases the baseline low. daily_energy_vs_temp now keeps
a day only when its samples cover at least min_coverage of it (default 0.9). Coverage is the
samples present times the meter's interval (timegrid.interval_hours, the modal step), over the
day's hours. With the site's zone a daylight-saving day is as long as its clock: 23 or 25 hours,
a repeated-hour sample counting twice. Without a zone every day is 24 hours, and the 23-sample
spring-forward day still passes 0.9. mandv.intervalfit.day_coverage gives each day's share.
Dropped days are counted in the frame's attrs["dropped_days"], and the results report them:
daily_changepoint_savings: a savings caveat;- the non-routine detectors:
n_days_dropped; - a config's
mv_baselinefinding: the metricn_days_droppedand a caveat; - the
mv_savingsfindings: a caveat for dropped baseline or reporting days.
The threshold is the config key mv[].min_coverage, a number from 0 to 1; billing entries
already had one. min_coverage=0 keeps every day, the frame before 0.105. Frames of whole days
(the BDG2 benchmark keeps complete days first) are unchanged.
daily_energy_vs_temp and hourly_energy_vs_temp default to rate_is_energy_rate=True (the
meter is a rate), while daily_changepoint_savings, towt_savings_hourly and the non-routine
detectors default to False (energy per interval). The defaults are historical and are kept;
pass the flag explicitly.
Implausible temperatures (0.105, #159)
A weather or BAS export sometimes writes a placeholder, such as -237, for a missing outdoor
temperature. Left in a fit, it is the coldest point: TOWT took it as its first temperature
breakpoint, and a heating change-point model bent its arm toward it. Every baseline fit now
screens its temperatures first. fit_towt, models.fit_model / best_model,
degreeday.fit_mean_temp_degree_day and the intervalfit frame builders treat a value outside the
sensor-health outdoor-air range (sensorhealth.PHYSICAL_BOUNDS, -40 to 140 °F) as missing. The
count is on the model (n_temp_screened, serialised only when non-zero), on the frame
(attrs["n_temp_screened"]) and in the savings caveats. temp_bounds=(lo, hi) sets another
range, and (-inf, inf) turns the screen off.
A row with no temperature has no weather to project. TOWTModel.predict used to give such a row
its time-of-week level alone; it now returns NaN for it. stats.avoided_energy_savings leaves the
row out of its sums, as before, and its caveat now says how many rows had no finite projection.
At prediction time too (#168). A fitted model screens the temperatures it is asked to predict
with the bounds it was fitted with: TOWTModel, ChangePointModel, MeanTempDegreeDayModel
and the CalTRACK Daily, Billing and Hourly models predict NaN for a value outside them instead of
extrapolating to it, and return_counts=True counts it as n_temp_screened. The coverage check
treats such a row as a row without a driver, not as an extrapolation, so one placeholder cannot
make a saving "severe". A model records temp_bounds in its as_dict only when they are not the
default range; a model stored before 0.105 predicts with the default range. When no reporting
row is left to sum (every temperature missing or screened, say), avoided_energy_savings
declines the saving with a reason instead of reporting zero.
Why no model could be fit (0.105, #160)
best_model tries each kind in kinds and keeps the lowest BIC. When none can be fit it used
to raise a bare ValueError("no model could be fit"). It now raises models.ModelFitError, still
a ValueError, whose message names every kind with its parameter count and the reason it was
refused: the fit's own error (for example need >=3 finite points to fit), n - p < 1 with the
counts, or a non-finite BIC. The same list is on the exception's candidates.
best_model(..., return_candidates=True) returns (model, candidates): one dict per kind tried,
in order, with kind, p and either n, sse, bic and selected or refused. The selection
itself is unchanged, with the same BIC and the same tie rule (within 1e-9, the first kind
tried wins).
_mvform.best_billing_model, the billing selector between the best change-point model and the
degree-day model at the bills' bases, raises the same ModelFitError when neither can be fit:
the change-point kinds as above, then the degree-day kind with its error or the caveat that
refused it (a slope of the wrong sign).
When no points were left (#172, #175). If the day-coverage rule, the temperature screen or
missing values left too few points to fit, the message says so after the list. It states what
the fit itself saw, the same for every candidate, then why the other rows were lost: "every
candidate saw 0 finite (temperature, energy) point(s), fewer than the 3 a fit needs; why: 20
day(s) dropped by the day-coverage rule (min_coverage) before the fit". The causes are rows
missing a temperature or energy value, temperature values screened, days dropped by the
day-coverage rule and bills dropped for temperature coverage. The exception's causes holds the
counts (None when points were not the problem), and upstream_given says whether the frame
builder's counts were available.
best_model counts the rows it screens and finds missing itself. The days or bills dropped
before the call are counted by the frame builder in the frame's attrs (dropped_days,
dropped_bills, n_temp_screened), and best_model finds them in any of these:
- the frame itself:
best_model(frame)fits itsoatandenergycolumns and takes its index astime_index; - its columns as pandas objects:
best_model(frame["oat"], frame["energy"])(pandas carriesattrsto a column); upstream=frame.attrs(orupstream=frame) when the data are NumPy arrays.
Without any of these, the message says that rows dropped before the call are not known, instead
of implying that there were none. upstream only feeds the message; it never changes the fit.
The billing selector best_billing_model(frame) takes the bills frame and always reads its
attrs.
TOWT options (0.105, #154, #155, #162)
All three are opt-in; with the defaults every number is unchanged.
Unseen hour-of-week bins (#154). TOWTModel.predict(index, temp) raises when a timestamp
falls in an hour-of-week bin the fit never saw: the one-hot design has no column for it, so the
prediction would collapse to the temperature term alone (a weekday-only fit projected onto a
weekend predicts −1.2 where the truth is 40). predict(..., unseen="fallback") predicts such a
row instead, in two steps:
- The unseen bin takes the occupancy class held by the majority of the seen bins at the same hour of day on the same day type (Monday–Friday, or Saturday–Sunday). The row is predicted as the seen bin of that hour, class and day type on the nearest day of the week (counted around the week; a tie takes the earlier day), with that bin's level and its class's temperature response.
- With no such donor (no seen bin at that hour on that day type, or a tie between the classes), the row is the mean of the predictions of every seen bin at the same hour of day.
A bin with no seen bin at its hour of day at all predicts NaN. return_counts=True returns
(prediction, counts) with n_unseen_fallback, n_unseen_hour_mean, n_unseen_unfilled,
n_clipped and n_no_temperature, as CalTRACKHourlyModel.predict(return_counts=True) does.
TOWTAtIndex(model, index, unseen="fallback") carries the option into
stats.avoided_energy_savings, whose caveats count the filled rows, and into the exact kernel,
whose design rows are the fallback's. towt_savings_hourly(..., unseen="fallback") also accepts
a baseline missing some hour-of-week bins (each bin present still needs min_obs_per_bin). Filled
rows are not fitted levels: coverage grades them unsupported, so a period with many of them is
declined as severe extrapolation by the default policy.
Non-negative predictions (#155). predict(..., clip_negative=True) sets negative predictions
to zero, as LBNL's RMV2.0 does for its prediction period; ChangePointModel.predict and
MeanTempDegreeDayModel.predict take the same option with return_counts=True for the count, and
so do the CalTRACK Daily, Billing and Hourly predicts (#171).
Clipping comes after the linear projection X @ beta: the projection variance and the exact
kernel are computed on the unclipped projection, and a bound TOWT's savings caveat says how many
projections were clipped.
Fixed knots, weights and the LBNL reference (#162). fit_towt(..., knots=[...]) replaces the
n_temp_segments quantile breakpoints with fixed temperature knots: k knots give k + 1
segments whose outer two are unbounded, so the first and last slopes continue beyond the fitted
range — the component temperatures of Mathieu et al. (2011), section 4.2 and Table 3, and RMV2.0's
piecewiseVariables. knot_min_obs drops an outer knot with fewer than that many temperatures
beyond it, keeping at least one. fit_towt(..., weights=w) fits by weighted least squares
(weights normalised to mean 1; equal weights are the unweighted fit exactly); the exact kernel
then reads the weights as variance weights and a reporting hour as one of average weight.
towt_lbnl_config() returns the settings verified against LBNL's RMV2.0 R package (version 1.1.0,
R/towt_baseline.R) and Mathieu et al. (2011), LBNL-4944E:
| Setting | Value | Source |
|---|---|---|
| knots | 40, 55, 65, 80, 90 °F (units="degC" converts) |
RMV2.0 makeBaseline |
| outer segments | unbounded | Mathieu et al. §4.2, Table 3; RMV2.0 piecewiseVariables |
| knot pruning | drop an outer knot with < 20 temperatures beyond it, keep one | RMV2.0 fitLBNLregress |
| occupancy split | separate occupied and unoccupied temperature responses | RMV2.0 fitLBNLregress |
| negative predictions | set to zero | RMV2.0 fitLBNLregress |
| recency weight | s² / (s² + Δt²), Δt in days from the fit's centre, s = 14 days |
RMV2.0 makeBaseline |
from camber.mandv.towt import fit_towt, towt_lbnl_config

cfg = towt_lbnl_config()
w = cfg.time_weights(energy.index, energy.index[-1])  # lbnl_time_weights
model = fit_towt(energy, temp, **cfg.fit_kwargs(), weights=w)
pred = model.predict(index, reporting_temp, **cfg.predict_kwargs())
A model fitted this way is still a CAMBER TOWT, not RMV2.0's. Not reproduced: RMV2.0's occupancy rule (an interval is occupied when a load regression on temperature, hinged at 50 and 65 °F, under-predicts it more than 65 % of the time), its ensemble of locally weighted fits (one fit centred about every 14 days, the predictions averaged with the same weight function), its 15-minute time-of-week intervals (the same as hour-of-week bins on hourly data) and its NaN for an unseen time of week. The Mathieu et al. paper itself differs again: six equal-width intervals over the facility's temperature range, a manually set occupied period and a single unoccupied slope, and no time weighting. The RMV2.0 variant below reproduces all four. Use it for a like-for-like comparison with RMV2.0, and in place of one recency-weighted fit centred on the end of the baseline, which drifts when the reporting period is long (see Horizon for its own reach).
TOWT (LBNL RMV2.0 variant) (0.105, #165)
camber.mandv.towt_rmv2.fit_towt_rmv2(energy, temp) reimplements RMV2.0 1.1.0's makeBaseline
(R/towt_baseline.R at commit 979a963, LBNL-ETA/RMV2.0). It is opt-in, and every other TOWT
is unchanged. Each step was read from the R source; the line numbers refer to that file:
| Step | RMV2.0 | Lines |
|---|---|---|
| time of week | 1 + floor((1440·wday + 60·hour + min) / intervalMinutes), default 15 minutes |
239–240, 48 |
| occupancy | OLS of load on 1, min(T − 50, 0), max(T − 65, 0) (°F), unweighted, all rows; an interval is occupied when more than 65 % of its residuals are positive |
186–220, 293 |
| occupancy split | used only when more than two intervals are occupied; otherwise one model | 297–302 |
| temperature | knots 40, 55, 65, 80, 90 °F, outer segments unbounded; an outer knot with fewer than 20 temperatures beyond it is dropped | 163–181, 306–343, 456 |
| local fit | weighted least squares, separate occupied and unoccupied regressions, one level per interval | 355–402 |
| centres | nsegments = max(1, ceiling(span_days / 14)); nsegments + 1 training rows evenly spaced by row count, first to last (floor(sort(n − w·(0:nsegments)) + 0.001), w = (n − 1)/nsegments) |
427–435 |
| local weights | s² / (s² + (c_k − t_i)²), days, s = timescaleDays = 14 |
446–451 |
| prediction | each local prediction set to zero where negative, then Σ w_k p_k / Σ w_k with w_k = s² / (s² + (c_k − t)²) about the prediction time |
404–406, 454, 472 |
| unseen interval | NA in every local fit, so NA |
386, 399, 472 |
The centres lie within the training period. The occupancy rule and the knot pruning are unweighted, so every local fit shares one design. CAMBER factors that design once and solves each local fit as a narrow weighted problem (#176), with the same minimum-norm coefficients as a separate weighted least-squares fit per centre; a year of hourly data fits in about the time of one pooled TOWT fit.
from camber.mandv.towt_rmv2 import fit_towt_rmv2

model = fit_towt_rmv2(energy, temp)  # hourly; interval_minutes=15 for 15-minute data
pred = model.predict(index, reporting_temp)  # NaN at an unseen hour of the week
pred, counts = model.predict(index, reporting_temp, unseen="previous", return_counts=True)
model2 = type(model).from_dict(model.as_dict())
Options:
predict(..., clip_negative=True)is the default, as in RMV2.0. Withclip_negative=Falseon the training timestamps,predictgives RMV2.0's training fit, which is not clipped (line 473).unseensets what an unseen interval predicts:"nan"(the default) is NaN, as in RMV2.0'smakeBaseline."previous"copies the previous timestamp's prediction, astowt_baseline'sapprox(..., method = "constant")does (lines 119–124). A row after the last prediction stays NaN."raise"raises an error."fallback"uses the TOWT fallback rule above. It is not RMV2.0 and needs hourly intervals.return_counts=Truecountsn_clipped, the rows whose final prediction was clipped, as for the other models. It is 0 by construction, because each local prediction is clipped before the average.n_local_clippedcounts the rows where at least one local prediction was clipped (#178).local_predictionsandweightsreturn the ensemble's parts.TOWTAtIndex(model, index)binds the model forstats.avoided_energy_savings.units="degC"takes Celsius. The occupancy hinges stay at 50 and 65 °F.
Not reproduced.
towt_baseline's data cleaning (clean_eload,clean_Temp) is not applied; clean the data first. CAMBER's temperature screen applies instead;temp_bounds=(-80, 130)givesclean_Temp's range.- RMV2.0 loops forever when one knot remains and it has fewer than 20 temperatures below it. CAMBER keeps that knot.
- In a rank-deficient local fit, R's pivoted QR and numpy's minimum-norm least squares can predict differently.
- The interval length must divide a day. With the default, hourly intervals, a 15-minute timestamp falls in its hour's interval; RMV2.0 would call it unseen.
Cross-check. On synthetic data, the hourly, 15-minute-interval, sub-hourly,
unseen-interval and short-baseline cases match RMV2.0's own makeBaseline to 1e-8. The
comparison covers the predictions, the approx fill and the training fit. The test is
tests/test_mandv_towt_rmv2.py::test_matches_rmv2_makebaseline. It is dev-only and skipped
unless CAMBER_RMV2_RSCRIPT names an Rscript; set CAMBER_RMV2_SOURCE to a copy of
towt_baseline.R from that commit (its model functions need base R only). R is not a
dependency.
Horizon (#177). A prediction weights each local fit by s² / (s² + (c_k − t)²) about its
own time t, so it leans on the local fits centred nearest it. In the reporting period those are
the fits at the end of the baseline: 90 days after a one-year baseline, the last centre weighs
about 25 times the first, and the weights even out only slowly after that. This is how RMV2.0
itself behaves, not a CAMBER departure.
- Prefer it for short reporting horizons, the first weeks and months after the baseline, and where the baseline's recent conditions matter (a schedule or load change late in the baseline). On synthetic data with a shorter summer schedule, it did better than an unweighted TOWT over the first months.
- Compare it with an unweighted TOWT (
fit_towt) when the reporting period runs several months beyond the baseline into a season the baseline saw little of, or saw long before its end. There the prediction still rests mostly on the last local fits, and on the same synthetic data it was a little less accurate than unweighted TOWT five months and more after the baseline. - It still does better than one recency-weighted fit centred on the last baseline hour
(
towt_lbnl_config()), which ignores the earlier seasons. On a synthetic two-year series with a shorter summer schedule, fitting the first year and predicting the second gives an hourly CV(RMSE) of about 14.8 % with this variant, against 18.1 % with that single fit.
Change-point + driver models
When energy also follows a continuously varying driver — occupancy, production, operating hours,
a school-day flag — that driver belongs in the model (SEP 2019 Ed. 2 §5.4, and the multivariable
change-point form of §6.3.2 as summarised in the #21 plan). multivariable.fit_cp_driver_model(T,
drivers, y) (provisional) fits E = W(T; change points)·β + D·γ: one of the usual change-point
shapes plus linear driver terms, with the change points grid-searched with the drivers in the
design so a driver that co-varies with season is not absorbed into the temperature slope, and
the kind chosen by BIC with the drivers counted in p. The model takes rows [T, driver_1, ...]
as one 2-D array and carries the standard fit record, so coverage (per column and by leverage),
both savings kernels, model_regression_tests / sep_validity and as_dict / from_dict work on
it unchanged.
In a config (0.90), mv[].model: "cp_driver" fits this form on every mv path — the plain
run, each declared method, the adjustments ledger and the versioned baselines of camber mv —
instead of the temperature-only change-point model. mv[].drivers lists the driver columns:
"weekday"— 1 Monday to Friday, 0 at the weekend;"occupied_day"— 1 onmv[].occupied_weekdays(default Monday to Friday) except the dates inmv[].holidaysand the days ofmv[].holiday_calendar(0.93, below);"break_day"— 1 on an occupied day that falls inmv[].break_calendar(0.93, below);- the name of any mapped numeric role, e.g.
"occupancy": its daily mean. A day without it is left out, and a meter without the role mapped is declined, naming it.
{"class": "METER", "role": "power", "model": "cp_driver", "drivers": ["occupied_day"],
 "holidays": ["2019-07-04", "2019-12-25"], "method": "forecast",
 "period": ["2018-01-01", "2018-12-31"], "reporting_period": ["2019-01-01", "2019-12-31"]}
Holiday calendars and break days (provisional, 0.93)
mv[].holidays lists dates by hand. mv[].holiday_calendar supplies them from a calendar instead
(camber.calendars), and the two combine:
- a country code for the bundled public holidays:
"US"(federal, observed dates, 2011-2030),"NO"(Norway's helligdager and 1 and 17 May, 2000-2040) or"ES-<community>"(Spain's labour holidays per autonomous community, ISO 3166-2:ES codes such asES-CLfor Castilla y León, 2016-2026). Spain needs the community, because its holidays differ by region. Each file names its sources: 5 U.S.C. 6103 and Executive Order 11582 checked against every year OPM tabulates, the Norwegian statutes (LOV-1995-02-24-12 § 2, LOV-1947-04-26-1 § 1), and the annual BOE resolutions with their corrections.scripts/calendars_refresh.pyrebuilds them; {"country": "ES", "subdivision": "CL", "files": ["local.csv"], "dates": ["2018-09-08"]}adds CSV files and single dates. A file has adatecolumn (one day per row) orstartandendcolumns (an inclusive range per row), an optionalname, and#comment lines. Relative paths resolve against the config's folder. Local holidays, a site's closures or a university's academic calendar go here;camber.calendars.register_calendar(code, provider)plugs in any other source, for example a wrapper around the third-partyholidayspackage. CAMBER does not depend on it.
A day in a year the bundled calendar does not cover is left out of the model, as a day without a driver's data is. It is never treated as a day with no holidays.
Some days are neither a working day nor a weekend. During a school's term break, staff, cleaning
and after-school care keep part of the building running. The "break_day" driver is 1 on an
occupied weekday (not a holiday) that falls in mv[].break_calendar (the same spec form), so the
break gets its own coefficient:
{"class": "ELECTRICITY_METER", "role": "power", "model": "cp_driver",
 "drivers": ["occupied_day", "break_day"], "holiday_calendar": "NO",
 "break_calendar": {"files": ["school_breaks_2019_2020.csv"]},
 "period": ["2019-08-01", "2020-02-29"]}
Counting break days as holidays does worse than leaving them out. On the COFACTOR electricity
meters (August 2019 to February 2020, Drammen's published 2019-20 school calendar) that pushed the
schools' median CV(RMSE) up by 1.5 points, and the kindergartens', which stay open, up by 5.4. As
a break_day driver the schools' median fell by 1.2 points, and 15 of 16 met daily G14
acceptance instead of 13. Norway's public holidays alone lowered the median CV(RMSE) by 0.9 to
2.4 points for schools, kindergartens and offices in 2018; nursing homes, open every day, did not
move. On the Valladolid buildings (2016), the publisher's academic-calendar flag, written as a CSV
of dates, worked best as a break calendar next to the ES-CL holidays. CV(RMSE) came to 15.6 %
and 20.8 %, against 16.3 % and 28.8 % with the holidays alone, and 17.9 % and 31.0 % with a plain
weekday driver. The bundled Castilla y León calendar agrees with the publisher's flag on 43 of the
44 weekday holidays of 2016-2019. The exception is Monday 24 April 2017, Castilla y León's day
moved off a Sunday, which the publisher did not flag.
An occupancy-driven building often fails validity with the temperature-only form: the weekly
cycle is left in the residuals as noise, and autocorrelated noise at that. The driver form models
it. The mv_baseline finding then carries model_form, drivers and driver_coef. A frozen
driver model reads its own drivers, and the fit-frame sha256 covers the driver columns. Without
mv[].model nothing changes. "method": "auto" (whose proposal ranks temperature-only models) and
"standard_conditions" (whose normal_year holds temperatures, not standard driver values) are
refused with this form.
Billing data
Utility bills are not days. Each bill covers its own service period (28 to 35 days for most
meters, sometimes 8 or 60), and its energy belongs to that period's weather.
camber.mandv.billing.BillingSeries (0.90.1) pairs each bill with its own period's mean temperature
and heating and cooling degree-days, and expresses the energy per day so bills of different
lengths can be compared. Since 0.92 the rest of the M&V stack treats those rows as bills.
Fits weighted by days (provisional, 0.92)
A bill's per-day energy is the mean of its d daily values, so with independent daily noise its
variance falls as 1/d. Least squares weighted by d is then the efficient fit. It is also exactly
the ordinary fit of the bills expanded to their days: each day carries its bill's mean temperature
and per-day energy. An unweighted fit gives an 8-day bill the same say as a 62-day one.
fit_model/best_model(..., weights=days)fit every candidate kind by weighted least squares, including the change-point search. The weights are normalised to mean 1.sseis the weighted SSE, and the fit record keeps(X'WX)^-1and the mean bill length asweight_scale.fit_stats(..., weights=days)weights SSE and SST. The mean becomes total energy over total days, and NMBE becomes the bias of the bill totals (zero for a model with an intercept). ρ is estimated on the standardised residuals√w·r.regression_tests/model_regression_testsand the SEP verdict use the same weights, and so doesestimate_nre_indicator(its rate is per day).days=onavoided_energy_savings,forecast_savingsandbackcast_savings, anddays_baseline=/days_reporting=onchained_savings, sumdays × per-day value, so every total is in energy units. The energy share outside the model's support is weighted the same way. The G14 kernel countsmbills. In the exact kernel,g = Σ d_j x_jandV_noise = κ s² c Σ d_j, wherecis the fit's mean bill length (weight_scale; 1 for a model fitted on daily rows).select_methodweights a frame whoseattrs["billing"]is set (whatenergy_vs_tempreturns), or any frame givendays="days". A bill counts toward a window only when it both starts and ends inside it.- The non-routine detectors fit their billing baselines with the same weights.
Equal weights are neutral. The fit takes the unweighted path byte for byte and only records
weight_scale. Daily and hourly callers pass no weights, so their results, and the gated BDG2
benchmarks, do not move.
Evidence (synthetic, tests/test_mandv_billing_wls.py and a larger scratch run). Bills of
uneven length were drawn from a daily truth with AR(1) noise, and 10% was saved in the reporting
year. Over 1,000 runs:
| Savings error (RMSE) | Mean error | G14 90% band covers | Exact 90% band covers | |
|---|---|---|---|---|
| Unweighted fit | 1,937 | −69 | 93.6% | not usable (see below) |
| Days-weighted fit | 1,907 | +23 | 92.3% | 89.9% |
The exact kernel scales its noise term by the fit's mean bill length, which only a weighted fit
records. An unweighted fit on bills, projected with days=, is treated as if it had been fitted
on daily rows, and its band covered only 65%. Fit bills with their days.
For a linear (2P) truth, the weighted slope's RMSE is 11% lower (0.132 vs 0.149). With a change-point truth the weighted change-point slope is no better: a long bill that spans the change point averages a nonlinearity (Jensen's inequality), and weighting gives such bills more say. The saving, which is what is reported, still improves.
In a config (provisional, 0.92)
An mv entry with bills runs the M&V flow on a bills CSV. It needs no trended equipment, and a
config with no equipment needs no source:
{"site": "Example office", "shared_oat": {"file": "oat.csv"},
 "mv": [{"bills": {"file": "gas_bills.csv", "energy": "therms", "estimated": "read_type"},
         "name": "Gas meter", "period": ["2019-01-01", "2021-12-31"],
         "reporting_period": ["2023-01-01", "2023-12-31"], "method": "forecast",
         "kernel": "exact", "validity": "both"}]}
billsis a file path, or{"file", "start", "end", "energy", "estimated", "units", "units_column", "end_inclusive", "merge_estimated", "heat_content", "enthalpy"}. The defaults are the columnsstart,end(the last day served, inclusive),energy,estimated(optional:true/false,yes/no,1/0,E/A) andunits(optional; one unit per file).namelabels the findings (default: the file's base name).- Estimated reads. An estimated read is the utility's guess, and the next actual read trues it
up.
merge_estimated(defaulttrue) merges each run of estimated bills into the next actual bill: one period, the summed energy. An estimated bill that no contiguous actual read follows (the last bill, or one before a missing bill) is dropped. Themv_baselinefinding reports both counts (estimated_merged,estimated_dropped) with a caveat. Withfalsethe estimates are kept as billed and flagged. - Temperature. The entry's
oatis{"file": ..., "timezone": ...}, or an opt-in fetch{"fetch": "auto" | "isd" | "nasa_power" | "open_meteo", "latitude", "longitude", "tz", "cache_dir", "offline"}(see WEATHER.md). Since 0.94 a fetch may name a"place"(an airport code or a city) instead of coordinates, and it follows the config's weather privacy ("weather"; a private facility defaults tooffline, see WEATHER.md). Without it, the config'sshared_oatis used.base_f(65) sets the degree-day base, or"auto"chooses separate heating and cooling bases from the bills (0.94; see below). A bill whose days are less thanmin_coverage(0.9) covered by temperature data is dropped and counted (bills_dropped). - Baseline. Energy per day against the bill's mean temperature, fitted with the best
change-point model weighted by days. It is judged at the G14 monthly thresholds (CV(RMSE)
15%) and needs
min_bills(9) bills wholly insideperiod. A baseline covering fewer than 330 days is flaggedshort_baseline. The finding carriesn_bills,n_days,hdd_total/cdd_total,oat_sourceandmean_bill_days. -
Savings.
method(forecast, backcast, chaining, standard conditions, orautofor the SEP proposal),kernel,validity,extrapolationandadjustmentswork as for a trended meter. Totals aredays × energy per day, andn_report_dayscounts days of service alongsiden_report_bills. The adjustments ledger sees the bills expanded to their days, so an entry is dated to the day it starts, not to its bill. An indicator estimated on bills marks a bill as inside the event by its start date. -
Units (0.92, #69). With a config
"units": {"system": "ip" | "si"}the savings, bands and adjusted figures are reported in kBtu or kWh, and the fit stays in the bills' own unit. The bills must then name a parseable unit. Gas billed by volume (Mcf, CCF, m3) needsbills.heat_content, such as"10.37 therm/Mcf"; there is no default. Withoutunitsnothing is converted. See UNITS.md.
Not supported for bills:
- model: "cp_driver": bills carry no daily driver values.
- interval.
With only 12 to 36 bills, rho is often not estimable, and the band is then unadjusted, with a caveat.
Degree-day bases chosen from the bills (provisional, 0.94, #72)
The 65 °F convention rarely matches a building. Internal gains, setpoints and the envelope set its
balance points, and heating and cooling usually balance at different temperatures. The
change-point models already find a balance point from the data. Before 0.94, though, the reported
hdd_total / cdd_total always used the fixed base_f, so they could contradict the model's own
change point. "base_f": "auto" chooses the bases from the baseline bills, and one set of bases
is used everywhere afterwards.
{"bills": {"file": "gas_bills.csv", "energy": "therms"}, "name": "Gas meter",
 "period": ["2019-01-01", "2021-12-31"], "reporting_period": ["2023-01-01", "2023-12-31"],
 "method": "forecast", "base_f": "auto",
 "base_search": {"heating": [40, 70], "cooling": [50, 80], "step": 1}}
Degree days from each day, not from the bill's mean. For every candidate base, each day's degree days come from that day's temperatures and are summed over the bill's service days. The day's temperatures are its hourly values when the series is sub-daily, and its daily mean otherwise. Degree days computed from a 30-day bill's mean temperature undercount the swing days. A shoulder-month bill whose mean sits above the base still has cold days below it.
On synthetic buildings with known bases (58 / 68 °F, daily noise), the same regression at the true
bases was compared on shoulder-month bills (a mean within 8 °F of a base). With degree days built
from each day, the per-day RMSE was about 1.7. With degree days from the bill mean it was about
5.0. The daily-built model was better on every one of 40 seeds (tests/test_mv_billing_bases.py
and a scratch run).
The search (camber.mandv.basetemp.select_bases) tries three degree-day kinds:
- DD-H: E/day = b + a·HDD/day, heating only;
- DD-C: E/day = b + c·CDD/day, cooling only;
- DD-HC: E/day = b + a·HDD/day + c·CDD/day, with the heating base no higher than the cooling
base.
Each kind searches its own grid by least squares weighted by the bills' days. base_search sets:
- heating / cooling (°F ranges) and step;
- grid: "data": both ranges become the 5th to 95th percentile of the baseline's daily mean
temperatures;
- tolerance, flat_share, fixed_f, kinds and r2_min (described below).
A fitted base is a parameter. DD-H / DD-C have p = 3 and DD-HC has p = 5, the way a
change-point model counts its change points. BIC, the n − p of CV(RMSE), adjusted R² and the
regression tests all use these full counts. The tests are flagged as conditional on the bases.
Choosing. Within a kind the bases with the least weighted SSE win. For a fixed parameter count
that is also the highest R² and the lowest CV(RMSE), so R² is reported but adds no selection signal.
Across kinds, and against the change-point models, the choice is BIC with the full parameter
counts, exactly as best_model ranks change-point kinds. The degree-day model at the selected
bases is one more candidate; a change-point model can still win. These are the inverse models of
ASHRAE RP-1050 and ASHRAE Guideline 14-2014 (its whole-building regression and inverse-model
provisions). The paywalled text was not consulted, and no section number is claimed here
(unverified).
How the base was chosen (mv_baseline.metrics.base_selection):
- profiles.heating / profiles.cooling: for every candidate base, the weighted SSE, R²,
adjusted R², CV(RMSE), NMBE and BIC of the best fit at that base. For DD-HC the other leg's
base is profiled out, and other_base_f says where it landed.
- heating_range / cooling_range: the candidates within tolerance of the best,
n·ln(SSE/SSE_min) ≤ 3.84. That is the profile-likelihood interval at 95% (χ², one degree of
freedom). It is approximate, because the SSE is not smooth in a base. On synthetic buildings the
true base fell inside both ranges in 38 of 40 runs at moderate noise.
- flat: a range covering flat_share (half) of the grid or more means the bills do not pin the
base down, and a caveat says so. A base on the edge of the grid is a caveat too (at_edge).
- candidates: each kind's best fit, or why it was refused. A slope of the wrong (negative) sign
is refused at that base, and a kind with no logical fit on its grid is refused.
One base everywhere.
- The frame is rebuilt at the selected bases. hdd_total / cdd_total, the calendarized months,
the reporting-period rows, the standard-conditions (normal-year) projection and the SEP refits
all use those bases. A leg the selected kind lacks keeps fixed_f (65 °F).
- A reporting- or intermediate-period refit (backcast, chaining, standard conditions) uses the
baseline's bases. For standard conditions it uses the baseline's model form too, so that one
normal year can drive both models.
- A frozen billing baseline stores its bases, and a rebaseline that moves them records
bases_changed (see below).
Both results side by side. model_comparison has one row for each of:
- the five change-point kinds;
- the degree-day model at the fitted bases;
- the same kind at fixed_f.
Each row has p, R², adjusted R², CV(RMSE), NMBE, BIC and the G14 verdict, and selected marks
the chosen model. A row whose R² and CV(RMSE) / NMBE disagree carries mismatch: a high R² with a
CV(RMSE) or NMBE that fails, or a low R² with a CV(RMSE) that passes (a flat load that weather
barely moves). fixed_base repeats the fixed-base totals and fits.
R² thresholds. The SEP 50001 M&V Protocol (2019 Edition 2, dated October 2023, §6.4.1; the
same in the 2019 first edition) requires R² ≥ 0.50 for a valid adjustment model. This was checked
against the public DOE document. Under validity: "sep" / "both" that test is part of the SEP
verdict, as before. Under "g14" an R² below base_search.r2_min (default 0.50) is a caveat:
"weather explains little of the variation". It is not a refusal. Guideline 14's acceptance
criteria stay CV(RMSE) and NMBE, as cv_rmse_max_for applies them (the section number is not
verified against the paywalled standard).
Evidence on real meters (BDG2, examples/bdg2/billing_agreement.py, not gated). The daily
meters were re-expressed as 28 to 35 day bills and a 10% saving injected in 2017. Savings on the
billing path (fixed 65 °F and auto) were compared with the daily path. The figures are in the
0.94 CHANGELOG entry.
Calendarization (provisional, 0.94, #72)
BillingSeries.calendarize(temp=None, heating_base_f=65, cooling_base_f=65, max_gap_days=0)
prorates bills into calendar months the ENERGY STAR Portfolio Manager way (Technical Reference:
Thermal Energy Conversions, Figure 1 step 3). Each bill's energy (and cost) is divided by its days,
and each day goes to its month. A bill from January 15 to February 14 splits by its days in each.
- A month is complete when every day, the first and the last included, is served by exactly one bill.
- Gaps (unserved days) and overlaps (days served twice; a plain table may overlap, a
BillingSeriesmay not) are listed. Portfolio Manager computes no metric across either, so any gap or overlap longer thanmax_gap_dayssetsdeclined_reason, andannual()/total()are withheld. - Months touched by an estimated read, or by a merged run of them, are flagged
estimated. - With a temperature series, each month gets its mean temperature and HDD / CDD from the same daily series the bills are paired with.
The calendarized months are an output view: models are fitted on the bills' own periods, and a
month is never fed back into a fit. In a config, "calendarize": true (or
{"max_gap_days": n}) adds calendarized to the mv_baseline finding, at the entry's bases.
camber mv report always shows the months of a billing meter.
Cost (provisional, 0.94, #72)
bills.cost names a column of each bill's billed cost. Without it no cost is read, so an existing
bills file with a cost column, which the #71 scale check reads on its own, changes nothing. With
it:
- the mv_baseline finding carries billed_cost and unit_cost (blended, minimum, median and
maximum cost per billed unit). This is the same implied $/unit that the unit-scale check
screens;
- "avoided_cost": "bills" prices a forecast's saving at each reporting bill's own rate (billed
cost ÷ billed energy). Other methods use the blended reporting rate;
- {"rate": 0.14} states a rate per billed unit.
avoided_cost, avoided_cost_rate, avoided_cost_basis and avoided_cost_uncertainty (the
energy band times the rate) go on the mv_savings finding.
Versioned billing baselines (provisional, 0.94, #72)
camber mv freeze | rebaseline | adjust | propose | report | list | run now handle billing
entries, with the same --reason, --apply, workspace lock and audit rules as trended meters
(#48). A billing baseline is keyed (facility, name, "mv_bills").
- freeze. Fits the entry's
period: the bills wholly inside it,autobases selected there. The length rule reads the bills' own span, so a bill straddling the period's edge is not a gap. The record'sprovenance.billingkeeps: - the bills (start, end, days, energy, estimated flag and cost), the unit and the merged estimated reads;
- the weather basis (source,
min_coverage, how the degree days were built); - the bases and the full selection profile.
The fit-frame sha256 also hashes the bills' days and degree days.
- run / report. Measure the reporting bills against the in-force version at its bases,
never re-selected. Triggers work as for a trended meter: T2 (declared events), T3, T4 and T5.
T1's daily step detection needs two segments of min_segment_days rows, which bills rarely
have, so declare changes in mv[].rebaseline.events. Since 0.95 a billing entry can opt in to a
step test built for bills (rebaseline.bill_steps, see
Step changes on bills). A blocking trigger cuts
the saving at its date.
mv report chains the versions. Its CUSUM rows are bills (energy per bill). It adds each
version's bases, the avoided cost per link and the calendarized months.
- rebaseline. Since 0.95 the window is searched when --period is not given (see
the window search); --period still
names one by hand. auto bases are selected afresh on the new window. A change of bases is
recorded as bases_changed (from → to) in the provenance, shown in the change row and audited
with the operator's reason.
- adjust. Records ledger entries as for a trended meter. An indicator is estimated on the
bills, weighted by their days.
Rebaseline windows of whole bills (provisional, 0.95, #74)
When a rebaseline-class trigger is unresolved, camber mv propose now searches a new baseline
window for a billing meter, as it does for days (camber.mandv.billwindow.new_bill_window).
camber mv rebaseline without --period uses the same search.
Candidates. For each bill, from the latest backwards, the candidate is the window that ends
with that bill and starts at the latest bill that still gives at least min_baseline_days (365)
days of service. That is the shortest run of whole bills covering a full service year. The
window's dates are its first bill's start and its last bill's last day, so no bill straddles an
edge.
Rules, those of the daily search:
- it starts at least settle_days after the trigger it answers (the latest blocking trigger, as
for days);
- it overlaps no ECM installation window (ECM date ± settle_days), and contains no declared
event (± settle_days);
- it holds at least min_bills (9) bills;
- the days its bills do not serve are at most max_missing_frac (10%) of its span. These are the
gaps between bills and the bills dropped for too little temperature coverage. This is the rule
every billing freeze already applies;
- its model is valid under require_validity, and it covers the conditions seen: the #20 tier of
every bill's rows at the new model's bases is not severe.
Each candidate is fitted the way camber mv rebaseline --period fits it, so base_f: "auto"
selects the bases on that window.
Ranking is the daily path's: the latest qualifying window wins. At most 12 candidates are
fitted, and after a failed one the search steps back one bill (the daily search steps back 30
days, about one bill). The proposal says so in a caveat. The window in --json adds
n_bills, the model's bases, ranking and tried (the number of fits) to the daily fields.
When no window qualifies yet, the proposal is declined with days_needed, or with the reasons
the candidates failed.
Step changes on bills (provisional, 0.95, #74)
The daily trigger T1 segments the reporting days' deviation from the frozen baseline by PELT,
with segments of at least min_segment_days rows. Bills rarely have 56 rows. Run on bills with a
short minimum segment instead, it raises far too many false alarms. In the simulation below, with
at least 6 bills a segment, 13 to 22% of meters with no change raised one within 36 bills, and 49
to 62% with 3.
"rebaseline": {"bill_steps": "scan"} (or {"min_run": 6, "threshold": 3.75}) replaces it for
a billing entry with a test built for bills (camber.mandv.billsteps). It is opt-in: without
the key nothing changes.
- The series. Each bill since the baseline ended gives
x = E / P − 1: its energy per day relative to the frozen baseline's projection for it. Each bill is weighted by its projected energy (days × projection). A segment's weighted mean is then its fractional deviation in energy,(ΣE − ΣP) / ΣP. A summer bill whose heating projection is near zero cannot swamp the test with a huge relative deviation. - The test. At every split with at least
min_run(6) bills on each side, the difference of the two weighted means over its standard error. The variance is pooled within the two segments and inflated by(1 + ρ)/(1 − ρ). ρ is the lag-1 autocorrelation of the within-segment residuals, corrected for its small-sample bias (ρ + (1 + 3ρ)/n, Marriott & Pope 1954). The largest value is compared withthreshold(3.75), and its split dates the step: the first bill after it. - Known changes are not steps. The series is cut at each ECM installation window and each
declared event (±
settle_days), and each stretch between them is tested on its own. An ECM's own saving, or a change already declared, is never detected again. - Outcome. As for days: a step of at least
major_step_frac(20%) of the projection calls for a rebaseline, a smaller one for an indicator NRA, and a step must be material (|delta| ≥ max(materiality, 2 SE)). The trigger'sbasisnames the test and whether its settings are the calibrated ones.
How the rule was chosen. A scratch simulation (not gated) built synthetic meters from daily weather: - an office, with heating and cooling change points; - a heating-only gas meter with little summer use.
Operations noise was persistent (daily AR(1), ρ = 0.9) plus independent day-to-day noise, at three levels. The baselines' monthly CV(RMSE) was about 3, 6 and 11% for the office, and 4, 7 and 13% for gas. The days were cut into bills of 28 to 35 days, and a baseline of 12 or 24 bills was fitted the way a billing entry is. A 10% ECM saving started with the first reporting bill, and a step of ±5, ±10 or ±20% started at reporting bill 12.
Each rule was looked at after every new bill, as a monthly camber mv propose would be, over 36
reporting bills. That is SEP's maximum achievement period (2019 Ed. 2 §4.2), after which T5 calls
for a rebaseline anyway. There were 300 seeds per cell.
The candidates, each calibrated to the same target of a false alarm on at most 5% of meters with no change over 36 bills: - the daily PELT as it is, with a minimum segment of 3, 4 or 6 bills; - a CUSUM of the deviations from their mean (Brownian-bridge statistic); - a self-starting tabular (Page) CUSUM; - the scan of the two-sample t described above, with and without the ρ inflation, and with 3, 4 or 6 bills a side.
The scan with 6 bills a side and the corrected ρ detected as much as any other and dated steps best. The CUSUM of deviations missed more. The tabular CUSUM alarmed later (median delays up to 18 bills) and dated steps poorly. With 3 or 4 bills a side every rule lost power.
The weights were chosen on the gas meter: - Weighted by days alone, the scan found a 20% step on only 30 to 52% of gas meters. - Weighted by projected energy, it found 61 to 97%, with the office figures unchanged within a few points. - Weighted by days × projection², the gas meters' false alarms rose to 8 to 56%.
The chosen rule at threshold 3.75. The false-alarm rate is over 36 bills. Detection is for the step at bill 12, and the delay is the median number of bills after the step.
| Meter | Baseline | Monthly CV(RMSE) | False alarms | 5% step | 10% step | 20% step | Delay (20%) |
|---|---|---|---|---|---|---|---|
| office | 12 bills | ~3% | 2.3% | 47% | 97% | 100% | 5 |
| office | 12 bills | ~6% | 4.7% | 18% | 64% | 98% | 6 |
| office | 12 bills | ~11% | 7.0% | 10% | 24% | 71% | 8 |
| office | 24 bills | ~3% | 5.7% | 62% | 99% | 100% | 5 |
| office | 24 bills | ~6% | 6.3% | 26% | 76% | 100% | 6 |
| office | 24 bills | ~11% | 6.7% | 14% | 32% | 82% | 7 |
| gas | 12 bills | ~4% | 0.7% | 3% | 35% | 92% | 6 |
| gas | 12 bills | ~7% | 1.3% | 4% | 21% | 79% | 9 |
| gas | 12 bills | ~13% | 8.0% | 11% | 21% | 61% | 10 |
| gas | 24 bills | ~4% | 1.0% | 4% | 43% | 97% | 6 |
| gas | 24 bills | ~7% | 1.3% | 6% | 28% | 85% | 9 |
| gas | 24 bills | ~13% | 12.7% | 15% | 26% | 67% | 10 |
Over all cells the false-alarm rate is 4.8%. The step was dated within two bills in 80 to 100% of detections at 20%, and 57 to 97% at 10%.
Where it falls short, and what to do instead. - A step becomes testable only once 6 bills follow it. A stretch is tested only once 12 bills follow the baseline, an ECM or a declared event, and a step within the first 6 bills of a stretch is never found. Detection takes half a year or more. - Steps of 5% are mostly missed at realistic bill noise, and 10% steps often; on the gas meter, whose summer bills carry little information, more so. - The false-alarm target holds only when the residuals are not strongly persistent. With the operations noise at daily ρ = 0.97 (slow drifts), 12 to 36 bills cannot tell a drift from a step. The rate rose to 22%, and 4 to 41% by cell (150 seeds a cell). The ρ correction cannot fix this with so few bills.
So declared events (rebaseline.events, T2) remain the recommended way to record a change on a
bill-only meter. The scan is a screen for large changes nobody announced, and every step it
raises is a claim to check against what happened at the site.
The degree-day model in the SEP method proposal (provisional, 0.95, #74)
With base_f: "auto", the baseline finding already chooses between the change-point models and
the degree-day model at the selected bases by BIC. From 0.95, method: "auto" (the SEP proposal,
select_method) offers the degree-day model as a candidate too, in every period: the baseline,
the reporting period and each intermediate window of a chain.
- One set of bases. Every period uses the baseline's selected bases, and its p counts them
(DD-H / DD-C 3, DD-HC 5).
- The criterion is the proposal's, unchanged: SEP validity (§6.4.1) first, then adjusted R²
with every fitted parameter counted (change points, and the degree-day model's bases). This is
the DOE EnPI tool's order. A fit with a slope of the wrong sign is left out, as in the baseline
selection. The finding states the criterion (model_criterion, and a caveat) and names the
candidate (degree_day_candidate). The baseline finding chooses by BIC, so the two can differ.
- Standard conditions need one normal year to drive both models. The reporting model there is
the best of the baseline model's form.
- camber mv propose does the same on a frozen version fitted at selected bases.
select_method(..., degree_day=False) leaves the model out.
With a numeric base_f, or bases that were not selected, the proposal is unchanged.
CalTRACK 2.0 methods
Provisional (0.105, #156). mandv.caltrack_daily and mandv.caltrack_hourly implement the
CalTRACK 2.0 Daily, Billing and Hourly methods as published: CalTRACK Methods 2.0 and its
Technical Appendix (openeemeter/caltrack at commit 6b630ee), with eemeter 2.10.0, the reference
implementation, for every point the documents leave open. Each rule in the code carries its id in
CAMBER's implementation spec (CT-D-* daily and billing, CT-H-* hourly, CT-C-* metrics), and
each constant (mandv._caltrack) cites its source.
| Method | Savings | Fit only | Model |
|---|---|---|---|
| Daily | caltrack_daily_savings |
fit_caltrack_daily |
CalTRACKDailyModel |
| Billing | caltrack_billing_savings |
fit_caltrack_billing |
CalTRACKBillingModel |
| Hourly | caltrack_hourly_savings |
fit_caltrack_hourly |
CalTRACKHourlyModel |
from camber.mandv.caltrack_daily import caltrack_daily_savings
from camber.mandv.caltrack_hourly import caltrack_hourly_savings

res = caltrack_daily_savings(
    baseline_energy, baseline_temp, reporting_energy, reporting_temp, fuel="gas"
)
print(res.model.model_type, res.model.heating_balance_point, res.model.r_squared_adj)
print(res.savings.avoided_energy, res.fsu["fsu"])  # CalTRACK's FSU, a fraction

hourly = caltrack_hourly_savings(baseline_energy, baseline_temp, reporting_energy, reporting_temp)
predicted = hourly.model.predict(reporting_index, reporting_temp)  # NaN where unseen
Every savings function returns a CalTRACKResult:
model: the fitted model. It haspredict(...)(days, bills or hours, with their temperatures),as_dict()andfrom_dict(), so a stored baseline can be projected later.sufficiency: the baseline data-sufficiency verdict and counts.savings: CAMBER'sSavingsResult, with the avoided energy summed over the reporting periods, the coverage grade, the caveats and the ASHRAE Guideline 14 band, as on every CAMBER savings path.fsu: CalTRACK's own fractional savings uncertainty, for Daily and Billing.fit: the baselineFitStats.reporting: the per-period table (observed, predicted, avoided).candidates: every candidate model with its status (Daily and Billing).
Inputs follow CAMBER's conventions. Naive timestamps are the site's wall clock, and timezone=
names it. Temperatures are °F and screened to the plausible outdoor range, at fit and at
prediction. A duplicate timestamp that is not a fall-back hour raises, since it may be two meters
in one series; without timezone= a fall-back hour cannot be told from a real duplicate, so any
duplicate raises and the message asks for the zone (#170). A month segment whose least-squares
solve fails is unfit with a reason, and the other months are still fitted (#166). Hourly
savings decline when no reporting hour can be predicted (#167). Every CalTRACK predict takes
clip_negative=True (#171).
Daily and Billing.
- Baseline window. The baseline is the 365 days before
intervention_start(default: the day after the last reading). At most 37 days may be missing. Electricity zeros count as missing. Negative values and values above median + 3 IQR are flagged. - Daily data. A day's usage is kept when at least half its intervals are present. The missing intervals are filled with the day's mean. A day's mean temperature needs at least half its hours. Temperature gaps of up to six hours are interpolated.
- Bills. Estimated reads are combined with the next bill, up to 70 days. Baseline bills under 25 days, or over 35 days (70 for bi-monthly), are dropped. A bill needs hourly temperature for 90 % of its hours.
- Candidates. The search fits intercept-only, HDD-only, CDD-only (electricity only) and
HDD+CDD on balance points from 30 to 90 °F. Each degree-day term needs 10 non-zero days (daily
only) and 20 degree days in total. A negative coefficient disqualifies a candidate. The
p-value screen is off at its default
max_p_value=1.0, as CalTRACK 2.0 removed it. - Selection. The qualified candidate with the highest adjusted R² wins. Ties go to the earlier candidate in eemeter's scan order.
- Billing fit. Billing fits usage per day by least squares weighted by each bill's days with a valid temperature.
- Prediction. A period's prediction is
n_days × (μ + β_H·HDD + β_C·CDD), with the degree days averaged over its valid days.
Hourly.
- Segments. There is one model per calendar month. It is fitted on its month at weight 1.0 and the months either side at 0.5. A segment needs consumption for over 90 % of the hours of its month and both neighbours, or it predicts NaN.
- Occupancy. An hour of the week is occupied when over 65 % of its rows are under-predicted by a preliminary model with heating below 50 °F and cooling above 65 °F.
- Temperature bins. The endpoints are 30/45/55/65/75/90 °F. A bin with fewer than 20 hours is merged by eemeter's rule.
- Design and fit. The design has 168 hour-of-week levels and the bins times occupancy, with no intercept. Each segment is fitted by weighted least squares, and prediction uses each hour's month model.
- Unseen hours. An hour of the week that a segment never saw predicts NaN, as in eemeter
3.1. eemeter 2.10 predicts its temperature terms alone there, which is a bug and is not
reproduced.
predict(...).attrsand the savings caveats count those hours. - Single model.
segment_type="single"fits one model on the year.result.sufficiency["single_model"]reports the two conditions under which CalTRACK allows it: at most two months with |NMBE| > 1 %, or reporting temperatures beyond 10 % of the baseline range.
Defaults follow the CalTRACK documents; eemeter_compat=True reproduces eemeter 2.10 where
the two disagree:
| Rule | Default (CalTRACK documents) | eemeter_compat=True (eemeter 2.10) |
|---|---|---|
| Missing baseline days | at most 37 of 365 | valid ≥ 90 % of 365 (at most 36) |
| Negative meter values | flagged; sufficiency passes | sufficiency fails |
| Day usage coverage | kept at ≥ 50 % of intervals | kept at > 50 % |
| Day mean temperature | ≥ 50 % of the day's hours | any hour (fit); > 90 % (sufficiency); bills > 12 hours |
| Temperature gaps ≤ 6 h | interpolated | not interpolated |
| Balance-point grid | 3 °F (21 points) | 1 °F (61 points) |
| Estimated bills | combined first, 70-day cap | length filter first, no cap |
| Bill temperature | all of the bill's hours | hours within 35 days of its start |
| Hourly month coverage | > 90 % per segment | not checked (a stub in 2.10) |
bp_step= overrides the grid either way. Where the documents and eemeter agree, or the spec
chose eemeter's reading, both modes behave the same:
- the billing degree days are the mean over the days with a valid temperature;
- the billing weight is those days;
- a coefficient of exactly 0 passes the sign test;
- an unseen hour of the week predicts NaN.
Uncertainty. result.fsu is CalTRACK's fractional savings uncertainty:
FSU = t·(aM² + bM + d)·CV(RMSE)·√((P/P′)(1 + 2/P′)/Q) / F
a,banddare the daily or billing coefficients.Mis the reporting months (reporting days / 30 for daily),Qthe reporting periods andFthe savings fraction.- The methods document never defines
P′. CAMBER follows eemeter:P′ = P(1 − ρ)/(1 + ρ), with ρ the lag-1 autocorrelation of the baseline residuals, andtonP − cdegrees of freedom. - Note
(1 + 2/P′), where Guideline 14's form, the oneresult.savingsuses, has(1 + 2/n)and the constant 1.26. - CalTRACK 2.0 publishes no hourly coefficients, so Hourly reports only the Guideline 14 band.
Its
pis the parameter count of all fitted segments.
Metrics (model.metrics) follow eemeter's conventions. cvrmse_adj is
√(Σe²/(n − c))/ȳ, and nmbe is Σ(ŷ − y)/Σy, positive when the model over-predicts: the
opposite sign to Guideline 14's NMBE in result.fit.
Points the spec left to interpretation:
- The baseline window for bills starts at the bill boundary nearest 365 days before the intervention (eemeter's overshoot).
- An estimated bill followed by another estimate is missing. Only the last estimate of a run is folded into the next actual read, which reproduces eemeter's documented example.
|NMBE|is the reading of the hourly 1 % rule.- A segment's month coverage counts the month's hours that fall inside the baseline window.
Cross-checking against eemeter
The CalTRACK 2.0 methods above are checked against eemeter 2.10.11 by
tests/test_caltrack_eemeter_xcheck.py, a dev-only test. With eemeter_compat=True, CAMBER
must match eemeter exactly on synthetic daily, billing and hourly cases:
- the selected model, its balance points, parameters and adjusted R²;
- the occupancy lookup, kept bins and parameter count of every hourly segment;
- every prediction both make.
The one expected difference is the unseen hour of the week, which is NaN in CAMBER. On the 0.105 cases the largest prediction difference was 2e-12 (daily and billing) and 3e-12 (hourly).
eemeter 2.x needs pandas 1.x and numpy 1.x, so it runs in its own environment and never
becomes a CAMBER dependency. The test runs eemeter there through tests/eemeter_oracle.py and is
skipped unless CAMBER_EEMETER_PYTHON points to that environment's interpreter:
python3.10 -m venv /tmp/eemeter-210 && /tmp/eemeter-210/bin/pip install \
  "setuptools<70" numpy==1.21.6 pandas==1.3.5 statsmodels==0.13.5 scipy==1.7.3 patsy==0.5.3
/tmp/eemeter-210/bin/pip install --no-deps eemeter==2.10.11
/tmp/eemeter-210/bin/pip install pytz click "pyarrow<15"
CAMBER_EEMETER_PYTHON=/tmp/eemeter-210/bin/python python -m pytest tests/test_caltrack_eemeter_xcheck.py -s
To compare savings on your own data, run the same baseline and reporting data through
caltrack_daily_savings(..., eemeter_compat=True) and through eemeter's
create_caltrack_daily_design_matrix and fit_caltrack_usage_per_day_model. eemeter reads the
last meter row as the end of the final period, so append a NaN row there. The models should be
identical. CAMBER's own daily_changepoint_savings and towt_savings_hourly are different
estimators, so expect only agreement within their bands.
Degree-day baseline on period-mean temperature (mandv.degreeday)
A degree-day regression E = base + a·HDD + b·CDD for monthly M&V when only an average
temperature and the energy per period are at hand (a lighter cousin of the change-point models
above). Each period's degree-days come from its mean temperature, about one balance point
shared by both legs. That is not the variable-base degree-day (VBDD, PRISM) model, which sums
daily degree-days over each period: a shoulder month whose mean sits above the base still has cold
days below it, and the mean-temperature form misses them. For VBDD on bills, with separate heating
and cooling bases, use mandv.basetemp (DD-H / DD-C / DD-HC, Billing data).
from camber.mandv.degreeday import fit_mean_temp_degree_day

m = fit_mean_temp_degree_day(tavg_per_month, energy_per_month)  # balance point by min CV(RMSE)
m.balance_point, m.cooling_slope, m.heating_slope, m.fit.cv_rmse
m.predict(normal_year_tavg)  # normalize / project the baseline
degree_days(tavg, balance_point) returns the (HDD, CDD) arrays. Flags: balance_point (fix it
or leave None to search), balance_range/step (search grid), kind (heating/cooling/both).
Fit statistics (R², CV(RMSE), NMBE, G14 acceptance) come from mandv.stats.fit_stats; their p
counts the intercept, the slopes and, when the fit searches for it, the balance point (as
basetemp counts its fitted bases; since 0.105, #163). A fixed balance_point is not counted.
Until 0.105 these were fit_degree_day and DegreeDayModel; both names still work and raise a
DeprecationWarning. Stored models keep "type": "DegreeDayModel" and read back unchanged.
IPMVP Option A — key-parameter measurement (mandv.option_a)
Measure the parameter that drives the savings and stipulate the rest (the classic lighting/motor retrofit): savings = measured Δparameter × stipulated duty.
from camber.mandv.option_a import option_a_savings, stipulated_annual_hours

r = option_a_savings(
    100, 60, stipulated_factor=stipulated_annual_hours(hours_per_day=10)
)  # baseline 100 kW, reporting 60 kW, 2600 h
r.savings, r.measured_delta, r.reduction_pct  # 104000 kWh, 40 kW, 0.40
Inputs may be scalars or sampled arrays/Series (the mean is taken). The result's basis records the
measured-vs-stipulated split for audit; the stipulated portion carries uncertainty this method does
not quantify. Complements Option B (mandv.retrofit_isolation) and Option C (mandv.stats).
Option D-style modeled savings (mandv.rc_model)
The one remaining IPMVP boundary, now shipped: a dependency-light 1R1C grey-box building model
(RCModel.predict(oat, schedule)) calibrated to metered energy (grid tau + OLS, gated by the same
ASHRAE G14 acceptance test), then run under an as-corrected control to give a pre-implementation
modeled saving with a G14 uncertainty band — the counterfactual the ecm_savings upper bound stands
in for. Refuses to claim a saving when the calibration fails the gate. So CAMBER now covers IPMVP
Options A, B, C, and D. A 2R2C thermal-mass variant (RC2Model/calibrate2), multi-zone
stacked-OLS calibration (calibrate_zones), and an optional EnergyPlus cross-validator
(interop.energyplus) add depth on the same grid-τ/OLS/G14 footing. See OPTION-D.md.
A claimed saving's basis reads "Option D-style modeled savings (calibrated 1R1C grey box;
pre-implementation estimate)" (0.105): IPMVP Option D is calibrated simulation, and a calibrated
grey box run before the change is made is reported in that style, not as Option D itself. The
calibration gate is fit_stats's, so NMBE is gated alongside CV(RMSE): CV(RMSE) ≤ 30 %
(hourly), |NMBE| ≤ 0.5 % and R² ≥ 0.75 must all hold.