Visualization
CAMBER's charts fuse graphing and diagnostics: every chart can surface the faults inside it,
and every fault can render the trend that proves it. All charts are matplotlib, draw onto a
supplied Axes, and lazy-import pyplot. The 0.2 MVP is the A → B → E → I slice plus a
self-contained HTML assembler; the primitives (load carpet, CUSUM, energy signature) shipped in
0.1.
flowchart LR
  df["role-frame (wide df)"] --> readiness["charts.readiness (A)"]
  df --> multitrend["charts.multitrend (B)"]
  df --> carpet["charts.carpet (E)"]
  df --> quality["charts.quality_dashboard (I)"]
  df --> diag["charts.diagnostic / oat_scatter"]
  rules["rules"] --> ev["Evidence (pattern J)"]
  diag --> ev
  readiness --> dash["build_dashboard / build_site_report"]
  multitrend --> dash
  carpet --> dash
  quality --> dash
  ev --> dash
  dash --> html["self-contained HTML (base64 PNG / inline SVG)"]
The MVP slice
| Pattern | Module | What it shows |
|---|---|---|
| A Ingest readiness | camber.charts.readiness |
per-point presence ribbon (green = data present) + coverage % |
| B Fault-annotated trend | camber.charts.multitrend |
synchronized multi-trend with rule-violation spans shaded |
| E Load carpet | camber.charts.carpet |
hour-of-day × date heatmap (occupancy, setback, stuck-on days) |
| I Data-quality dashboard | camber.charts.quality_dashboard |
points × {coverage, score, flatline, outliers} heatmap |
A — readiness ribbon
from camber.charts.readiness import readiness_ribbon

readiness_ribbon(df, max_bins=240)  # df: wide point/role frame
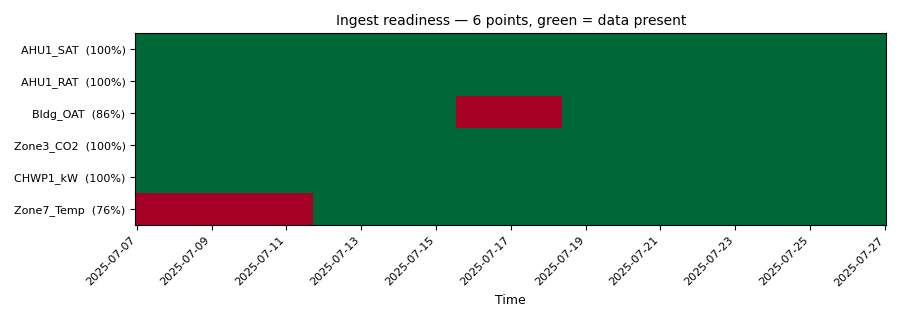
Synthetic data: six trended points over three weeks. The red blocks are a three-day gap in the outdoor temperature and a zone point that starts on day six; the percentages are each point's coverage.
Flags = max_bins (time resolution), title, max_xticks. presence_matrix(df) returns the
raw (matrix, bin_starts, coverage) if you want the numbers.
B — fault-annotated multi-trend
from camber.charts.multitrend import fault_multitrend

fault_multitrend(df, ["load_kw", "sat"], spans={"high_load": df["load_kw"] > 95}, normalize=True)
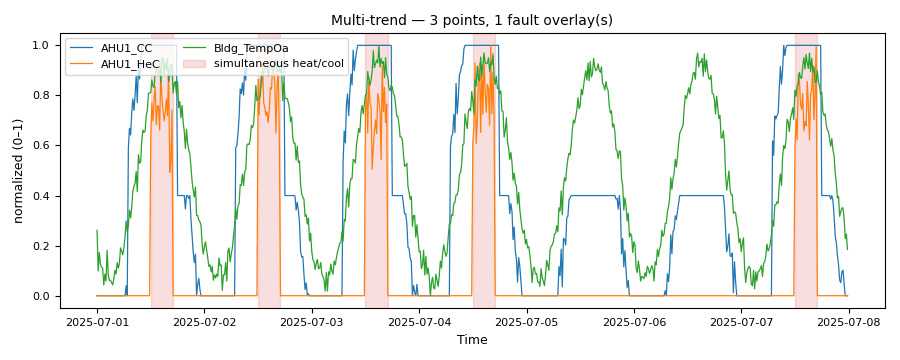
Synthetic data: camber.synth.make_ahu_trends(fault="reheat"), normalised to 0–1. The shaded spans are where a heating-valve-open and cooling-valve-open mask is true: simultaneous heating and cooling every weekday afternoon.
spans is {label: boolean Series} — each rule supplies the timestamps where it tripped, and
each True run is shaded once. Each flagged sample is shaded over its own interval, up to the next
sample, and a run splits at a data gap (a step longer than 2.5 times the median step), so missing
data is never shaded. Flags: normalize (overlay disparate units 0–1; "unit" scales series that
share a unit together, so a temperature keeps its place against its setpoint), shade_color,
shade_alpha, title. mask_to_spans(mask) is the reusable mask→intervals helper.
E — load carpet
from camber.charts.carpet import load_carpet

load_carpet(df["load_kw"], agg="mean", label="Load (kW)")  # hour of day x date
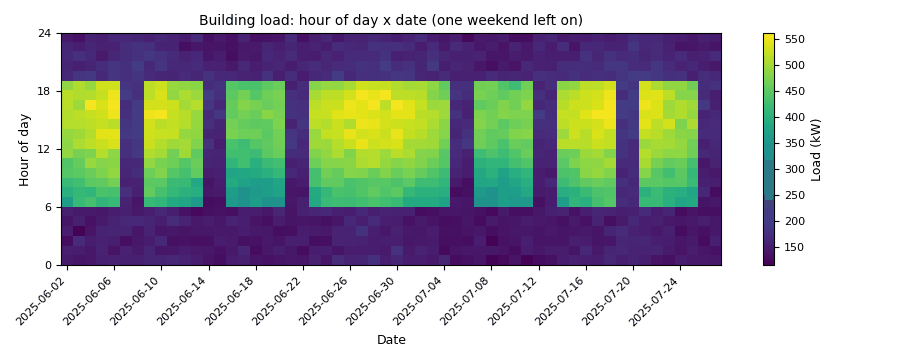
Synthetic data: eight weeks of hourly building load. Each weekday is a bright block from 06:00 to 19:00; the one weekend that runs a weekday profile joins two weeks into one long block.
Each column is a day and each row an hour, so the occupied schedule, the setback and a day the
building was left on read at a glance. Every calendar day from the first sample to the last has a
column, so a day with no data is a blank column and an outage shows as a gap. Flags: agg, cmap, label, title, max_xticks.
carpet_matrix(series) returns the raw (matrix, hours, dates).
I — data-quality dashboard
from camber.charts.quality_dashboard import quality_dashboard

quality_dashboard(df, metrics=("coverage", "score", "flatline_frac", "outlier_frac"))
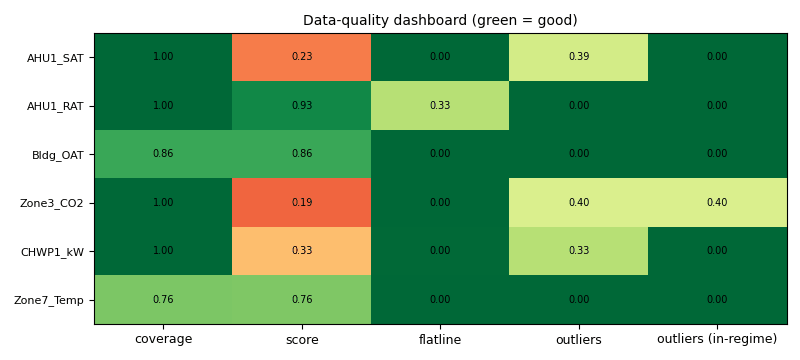
Synthetic data: the same six points as the ribbon, with the opt-in in-regime outlier column. The supply-air and pump points cycle, so their plain outlier share is high and their in-regime share is zero; the CO₂ spikes stay outliers in either read.
A heatmap colored so green = good for every metric (higher-is-better and lower-is-better are
both mapped correctly). Built from camber.ingest.quality.assess.
An opt-in fifth metric, regime_outlier_frac ("outliers (in-regime)"), reports outliers judged
within each regime of a duty-cycled point. Showing it beside outlier_frac is how a reader
sees a two-regime read rather than having it applied invisibly: a large gap between the two columns
means the point cycles. A metric that could not be computed renders blank rather than as zero.
Deepening the catalog (0.3)
Beyond the MVP slice, 0.3 builds the pattern catalog toward rules as a chart engine — every rule renders its own evidence. First renderer: pattern D.
D — OAT cloud-shape scatter
from camber.charts.oat_scatter import oat_scatter, classify_shape, brush_back

ax, shape = oat_scatter(load_kw, oat, ylabel="kW")  # overlays the change-point fit + guides
shape.shape  # "linear" | "hockey-stick" | "v" | "scattered"
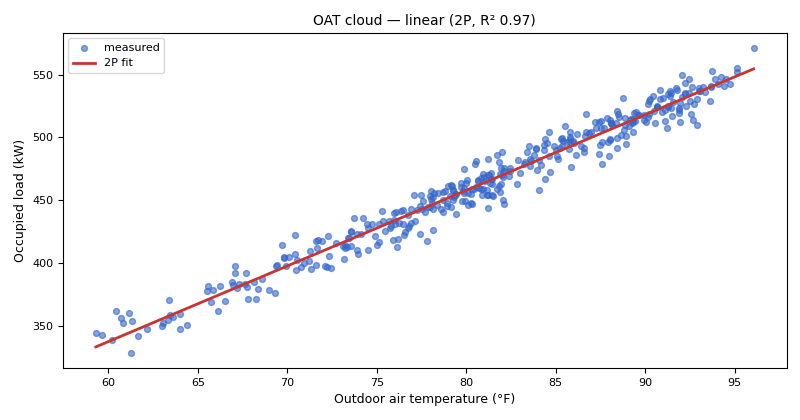
Synthetic data: six weeks of occupied-hour building load against outdoor temperature. oat_scatter overlays the best change-point fit and labels the cloud's shape (here linear, R² 0.97).
The shape of the cloud against outdoor-air temperature reveals control behavior a time-series
buries. classify_shape(series, oat) labels it from the fitted change-point model + goodness of fit
(a weak fit → scattered, i.e. no OAT dependence) with no chart required, returning a
JSON-friendly CloudShape. brush_back(series, oat, x_range=…, y_range=…) maps a selected region
of the cloud back to the timestamps that produced it — the primitive the interactive-linking
layer (below) uses to answer "when did this cluster happen?".
Flags: changepoint ("auto"/a kind/False), classify, by (colour by season/occupancy),
min_max_avg (per-point min–max whiskers — provenance over a bare average), cmap. Generalizes the
energy_signature plot to any point (airflow, valve %, ΔT), not just energy.
G — templated subsystem diagnostic scatters
from camber.charts.diagnostic import diagnostic_scatter, TEMPLATES

ax, violating = diagnostic_scatter(role_frame, TEMPLATES["sat_reset"])  # violating: bool Series
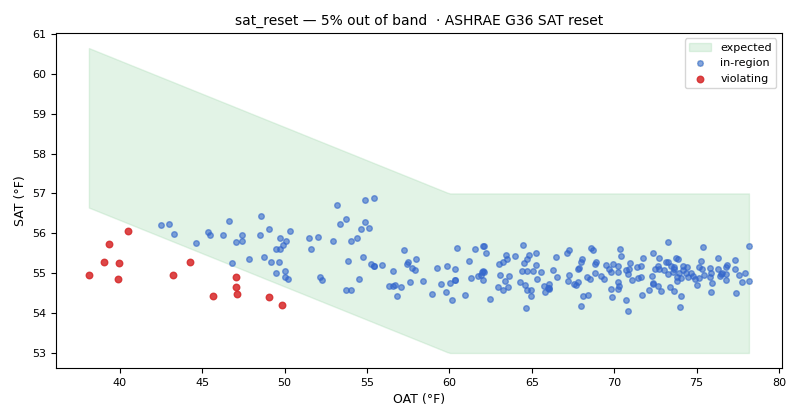
Synthetic data: a supply-air temperature held at 55 °F, on the packaged sat_reset template. The band rises as the outdoor air cools; the red points are the cold-weather hours the reset should have raised.
Each subsystem has an expected signature; a DiagnosticTemplate names two roles and an
expected(x) -> (low, high) band, and diagnostic_scatter overlays that band, shades the points
outside it, and returns the violating mask — so the figure doubles as a rule's evidence (feeds
pattern J). template_violations(frame, template) returns the same mask without plotting, so a
report or test can re-derive a verdict from the chart's own envelope. Packaged TEMPLATES:
sat_reset, chw_reset (reset schedules vs OAT — clamped at the
endpoints), economizer (OA damper open for free cooling, minimum when hot), no_simultaneous_hc
(heating valve must be ~0 when cooling is active). Build your own with band, reset_line,
economizer_template, no_simultaneous_template. Flags: shade, tolerance.
Plotting a drift baseline. Those templates all encode a band someone designed. fitted_band
encodes one the equipment earned — a frozen drift baseline's own fitted line
± k residual sigmas — so the comparison the drift detectors actually make (residuals against the
frozen line at matched load) becomes visible instead of staying inside the rule:
from camber.charts.diagnostic import diagnostic_scatter, fitted_band
from camber.store.modelstore import BaselineStore

model = BaselineStore.load("baselines.json").model_for("Site", "CH_1", "chiller_approach_cond")
ax, violating = diagnostic_scatter(current_frame, fitted_band(model, "tons", "approach_f", k=2))
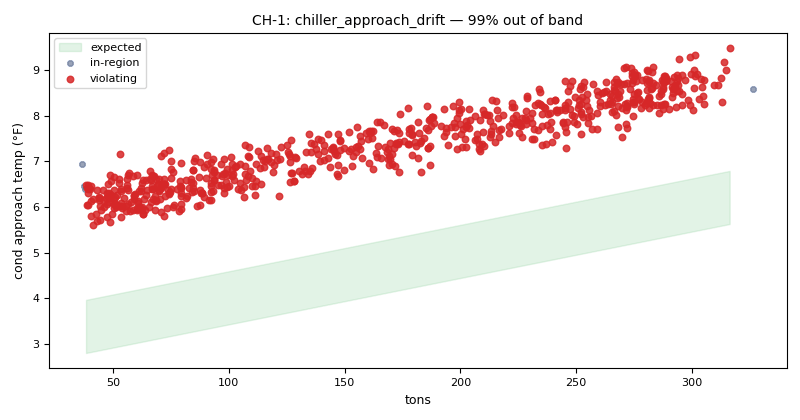
Synthetic data: driftsim with condenser fouling. The band is the frozen baseline's fitted line ± 2 residual sigmas; the current period's approach sits above it at every load.
Outside the load envelope the baseline was fitted on, the band is NaN: the shaded region shows a
gap and points there are not counted as violations. Judging a reading against an extrapolated
fit is the same asserted negative the drift rules refuse to make — pass within_envelope=False only
if you have a reason to extrapolate. k is a band width, not a severity threshold; the detectors'
own screening-grade sigma floors decide what warns or faults.
J — rules as a chart engine (the keystone)
Every rule that can mark its violating timestamps renders its own evidence — the chart is the audit evidence and the report figure. A rule opts in with an optional, duck-typed hook:
class SimultaneousHeatCool:
    def evidence(self, equip, frame):  # optional; rules without it are unaffected
        from camber.charts.diagnostic import TEMPLATES
        from camber.charts.evidence import Evidence

        return Evidence(renderer="diagnostic", template=TEMPLATES["no_simultaneous_hc"])
Evidence names a renderer (diagnostic / multitrend / oat_scatter / carpet) and the
roles / mask / template it needs; render_evidence(evidence, frame, ax=…) dispatches to that
pattern primitive. finding_evidence(rule, equip, frame) calls the hook safely (returns None when
absent or declined), and evidence_descriptor(evidence) is the JSON-friendly payload (renderer +
roles + violating timestamps) for export/linking. Finding carries an optional evidence field.
Every rule renders evidence. Rules with a tailored hook map to the fitting renderer and shade
the specific violation: simultaneous_heat_cool & outdoor_air_fraction (diagnostic),
supply_air_reset (diagnostic reset), reheat_penalty (OAT scatter — heating in warm weather),
night_weekend_setback (carpet — the fault is the schedule), overcooling_min_flow /
unmet_setpoint_hours / supply_air_control / airflow_tracking (multitrend, violating spans
shaded). Every other rule falls back to a default multitrend of the roles it examined — so the
whole library (present and future rules) carries evidence, no per-rule map required. Fleet findings
(no single equipment frame) render none.
Drift rules are the one family the default would misrepresent. Their claim is not "these values
are wrong" but "these values have moved off a frozen line", and a trend of the raw roles shows the
levels while hiding exactly that. So each of them declares
drift_signature() -> (kind, load_col, metric_col) and drift_frame(frame) instead of a bespoke
hook, and drift_evidence(rule, equip, frame) builds the chart the detector reasons about: the
current period scattered on its frozen baseline's fitted_band.
finding_evidence tries it before the default trend. A rule with nothing frozen returns None —
a scatter with no band would invite the reader to judge it by eye, which is the comparison the frozen
baseline exists to make. From the CLI: camber drift report … --charts.
The dashboard wires it automatically — pass rules=:
html = build_dashboard(df, findings=findings, rules=registry) # evidence=True by default
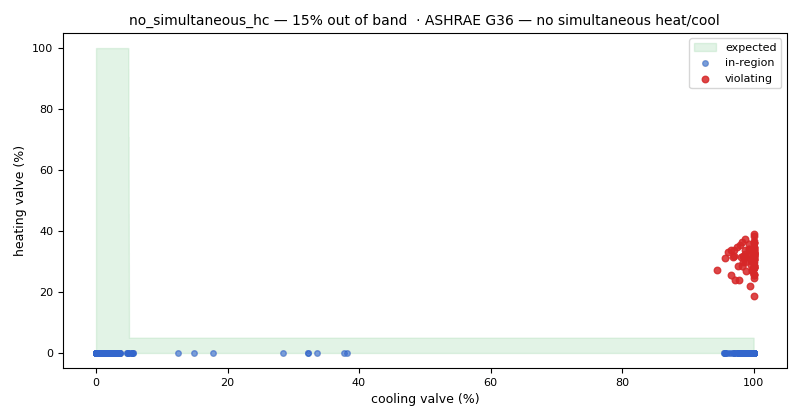
Synthetic data: the evidence chart simultaneous_heat_cool declares, rendered by render_evidence. Valves are in percent, and the red points are exactly the samples the rule counts: both valves above its 5 % open threshold during occupied hours.
Each actionable finding whose rule opts in renders its evidence chart under an Evidence section.
The Std-211 audit report does the same — AuditReport.to_html(rules=…, frames={equip: frame})
embeds each finding's evidence beneath the findings table (per-equipment frames, so a fleet audit
renders the right trend for each unit).
C — peer/cohort comparison + cohort-deviation rule
from camber.charts.cohort import cohort_small_multiples, cohort_deviation

fig, res = cohort_small_multiples(frames, Role.AIRFLOW)  # frames: {equip: role-frame}
res.outliers  # units > k robust-σ from the cohort norm
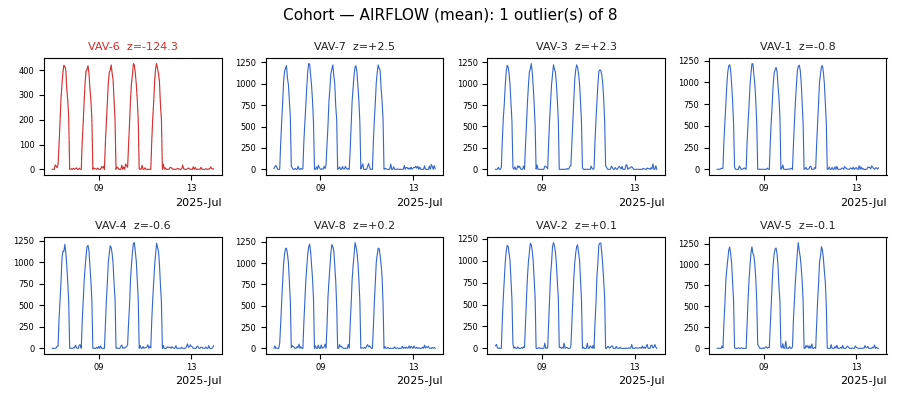
Synthetic data: airflow for eight boxes over a week. The box at about a third of its peers' airflow is ranked first and drawn in red.
Small multiples of a role across a cohort of like equipment, ordered by deviation (worst first),
outliers in red. Deviation is a robust z-score (median/MAD) of a per-unit summary (mean / peak
/ load_factor), so a couple of odd units don't move the reference. The same score powers a FDD
rule — camber.rules.cohort.CohortDeviation(role, k=…, summary=…) is a fleet rule that flags "this
unit runs unlike its peers", a signal no per-unit absolute-bound rule can see. Flags: k, summary,
min_cohort, rank, ncols, max_units.
H — M&V baseline, savings & uncertainty
from camber.charts.savings import savings_chart

ax, res = savings_chart(
    baseline_model, t_report, y_report, n_baseline=200, p_baseline=2, cv_rmse=0.08
)
res.avoided_energy, res.abs_uncertainty  # e.g. 2983 ± 1318 at 90%
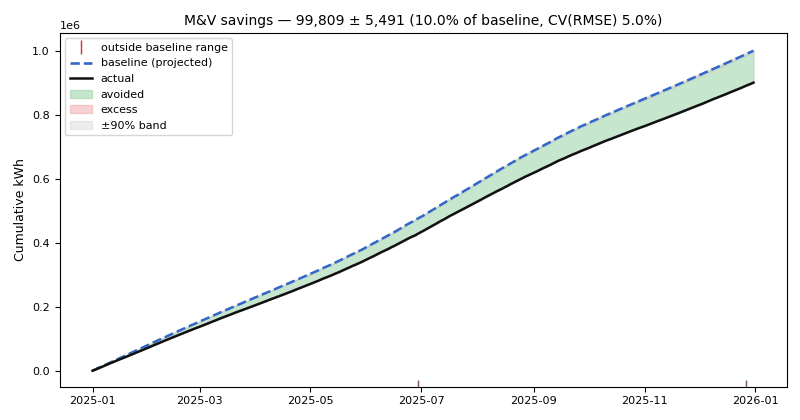
Synthetic data: a year of daily energy after a 10 % saving, against a change-point baseline fitted on the year before. The grey band is the G14 fractional savings uncertainty at 90 %.
The IPMVP Option-C picture: cumulative baseline-projected vs actual energy, the avoided energy
shaded between them (green = saved, red = excess), and the ASHRAE G14 Annex-B fractional savings
uncertainty carried as a ± band on the running total — savings and how sure we are of them. Fit
quality (CV(RMSE)) annotates the baseline's credibility. cumulative_savings(...) returns the raw
(index, cum_baseline, cum_actual, cum_avoided) arrays. Reuses mandv.stats.avoided_energy_savings
and any predict()-able baseline (mandv.models.best_model). Flags: confidence, rho
(lag-1 residual autocorrelation — raises the band; None, the default, leaves it unadjusted and
says so on the result), ylabel, extrapolation (the coverage policy).
The chart follows the baseline's coverage of the reporting period (MANDV.md):
| Coverage | Chart |
|---|---|
in_range |
as above |
moderate |
as above, the title suffixed "extrapolated: N% of points outside the baseline range", and the band widened by k |
severe, declined (default) |
actual energy plus the projection, dashed grey and labelled "extrapolated — not a saving"; no avoided/excess shading, no band; title "M&V savings declined — severe extrapolation of the baseline" |
In every state the reporting points outside the baseline support are rug-marked in red along the x-axis ("outside baseline range").
F — load profiles & load-duration curves
from camber.charts.loadprofile_chart import load_profile_chart, load_duration_chart

load_profile_chart(load_kw, split=True)  # weekday vs weekend hour-of-day shape
load_duration_chart(load_kw, price=0.15)  # LDC + energy-cost translation
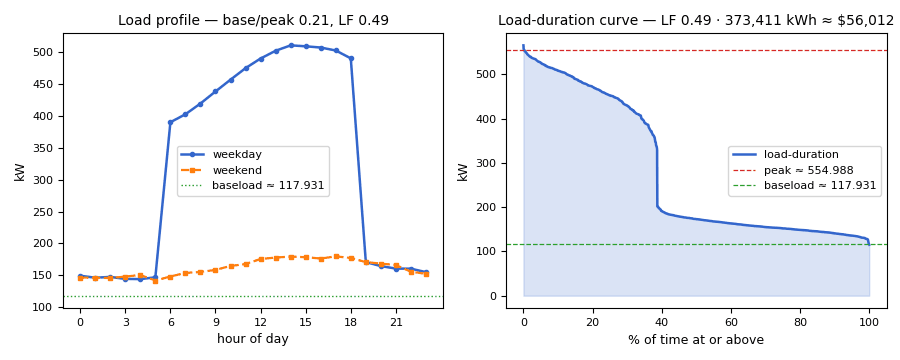
Synthetic data: eight weeks of hourly building load. Left, the weekday and weekend profiles with the base load; right, the load-duration curve with peak, base load and the energy cost at $0.15/kWh.
Two views on load shape. load_profile_chart plots the average load by hour-of-day (weekday vs
weekend when split, exposing schedule gaps) with the base load annotated. load_duration_chart
sorts every interval high-to-low against the % of time it's exceeded — the area is energy, the left
edge the peak, the right shoulder base load — and with a price ($/kWh) adds an energy-cost figure.
Both return (ax, LoadMetrics) and reuse camber.loadprofile. Flags: split, annotate, price.
Evidence uses the rule's own envelope. economizer_high_limit and outdoor_air_fraction draw
their evidence from the samples, basis and thresholds behind the verdict. That means the configured
high limit, minimum OA and differential changeover, not the generic TEMPLATES["economizer"]. They
hand the renderer a derived frame (Evidence.frame), so the red points are exactly the samples the
verdict counts. economizer_high_limit judges (and draws) fan-on samples only and reports the
samples each guard left out (n_masked_fan_off, n_masked_small_delta_t for |OAT − RAT| below
denom_min_f, n_masked_out_of_range). supply_air_reset shows the occupied, fan-on,
cooling-hour SAT-vs-OAT cloud its slope is fitted on, not a packaged reset band.
Box by hour
charts.box_by_hour(series, mask=fan_on) draws one box per hour of the day, using only the samples
where mask is true. A duct static that is never reset down overnight or at light load shows as one
flat band. Each hour is labelled with its sample count (red under 10), so a handful of
night-cycle samples is not read as a daily pattern. The RCx report uses it on the
air-distribution page.
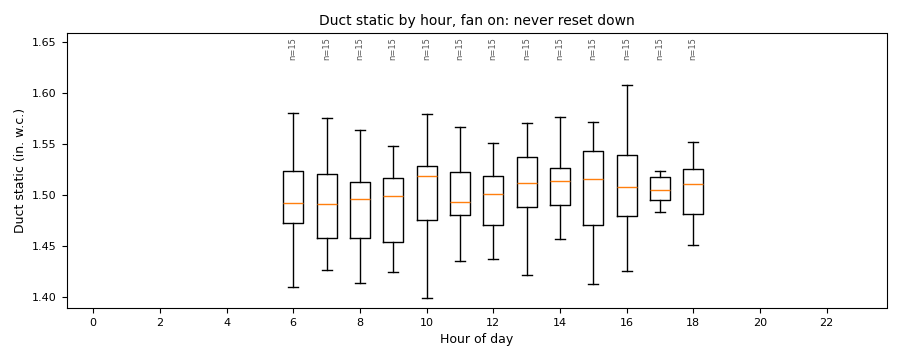
Synthetic data: duct static on fan-on samples, by hour of day. The same band at every hour is a static setpoint that is never reset; each hour is labelled with its sample count.
CUSUM and energy signature
The two M&V primitives from 0.1 draw what MANDV.md computes:
from camber.charts.cusum_chart import cusum_plot
from camber.charts.energy_signature import energy_signature

ax, model = energy_signature(daily_oat, daily_kwh)  # the best change-point model, overlaid
cusum_plot(projected, actual, limit=None)  # running sum of projected minus actual
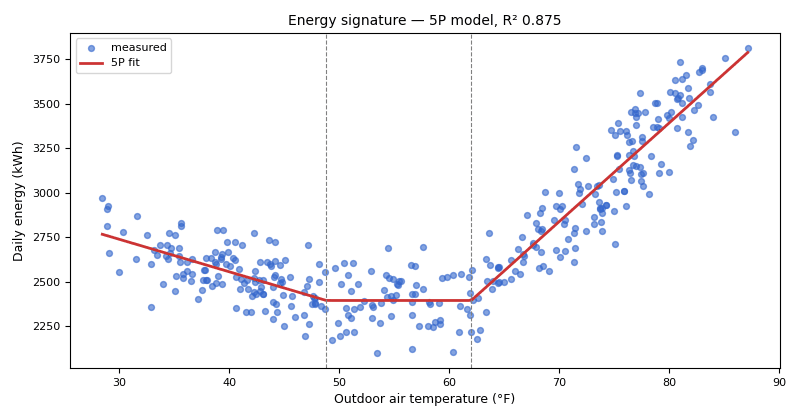
Synthetic data: a year of daily energy against outdoor temperature. energy_signature fits the best of the 2P to 5P change-point models (here 5P) and marks its change points.
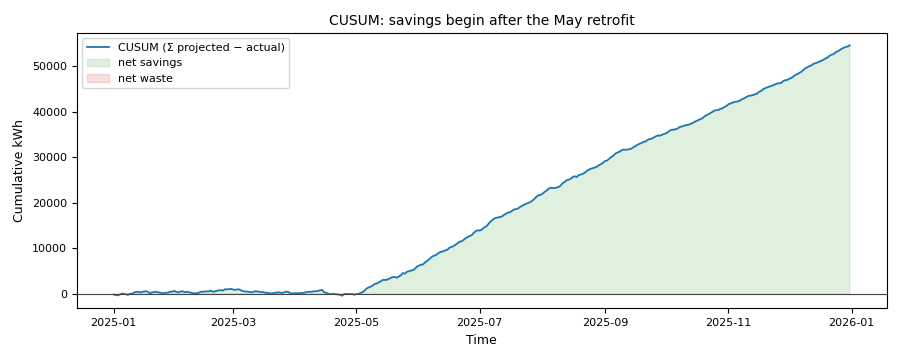
Synthetic data: the same building's next year, projected from that baseline. The CUSUM stays near zero until a retrofit in May, then climbs as the savings accumulate (green = net savings).
energy_signature takes model= to draw a fit you already have and kinds= to limit the
candidates. cusum_plot shades net savings green and net waste red; limit adds a ± control
band, and chained_cusum_plot draws one CUSUM across a chain of baseline versions.
The HTML dashboard
camber.report.build_dashboard assembles the sections + the ranked findings into one
self-contained HTML page — matplotlib figures inlined as base64 PNG, no web framework, no
external assets.
from camber.report import build_dashboard

html = build_dashboard(
    df,
    findings=findings,
    spans={"high_load": df["load_kw"] > 95},
    carpet_col="load_kw",
    rank_by="cost",
    title="Site dashboard",
)
open("dashboard.html", "w").write(html)
Option flags — build_dashboard
| flag | default | effect |
|---|---|---|
sections |
("A","B","E","I") |
which sections to render, in order |
findings |
None |
listed ranked beneath the charts (actionable only) |
spans |
None |
{label: boolean Series} shaded in section B |
rank_by |
"severity" |
findings order — "severity" or "cost" (annual $ if present) |
top_n |
20 |
max findings listed |
carpet_col |
first column | which point the carpet (E) draws |
multitrend_cols |
all | which points section B overlays |
normalize |
True |
normalize the multi-trend overlay |
rules |
None |
Registry / {name: rule} / rules — enables per-finding evidence (pattern J) |
evidence |
True |
render each actionable finding's evidence chart when rules is supplied |
interactive |
False |
add a brush-able inline-SVG scatter (vanilla JS, no framework) |
link_x / link_y |
auto | the scatter's axes (default: an OAT-like x, the first other column) |
data_sources |
None |
provenance dicts: the "Data source & licence" block first in the body (NC banner for research-only data) |
Interactive linking (brush → select)
html = build_dashboard(df, interactive=True) # link_x defaults to an OAT-like column
interactive=True the dashboard adds a brush-able scatter drawn by a small vanilla-JS
module (no framework, no CDN, CSP-safe) from an inline JSON payload. Drag a box over the cloud and the
selected points highlight while a linked readout lists their timestamps — the pattern-D brush-back
made live.
Cross-panel linking (0.8). The brush no longer stops at the scatter: a shared window.CAMBER
selection bus (a Set of selected timestamp strings) lets the selection propagate across every view.
Panels B (fault multitrend) and E (load carpet) are promoted from static PNG to inline SVG
that subscribe to the bus — brushing a cluster in the scatter shades the corresponding time ranges
in the multitrend and highlights the matching hour × date cells in the carpet. Every panel keys off
the same str(timestamp) from the frame index, so they interoperate without sharing a coordinate
system; panels A and I stay PNG (aggregate matrices, not timestamp-indexed). Still a single
self-contained CSP-safe file. selection_bus_html(), carpet_svg_html(series, …), and
multitrend_svg_html(df, cols, spans=…) build the pieces; interactive_scatter_html(...) the scatter.
Live web UI (0.72)
Everything above is a one-shot self-contained file. camber.api.ui adds its live counterpart:
a single vanilla-JS page served by the read-only API at GET /ui that fetches the running store
(/facilities, /points, /history) and polls, so the views refresh as new data lands
("continuous, not one-shot"). It reuses the same window.CAMBER selection bus — brushing the
synchronized multitrend links to a timestamp readout exactly like the static panels.
camber serve /path/to/store          # API + live dashboard: open the printed URL (?token=...)
camber serve /path/to/store --auth none    # no token: http://127.0.0.1:8080/ui
python -m camber.api.server /path/to/store 8080   # equivalent; JSON endpoints unchanged
Open the viewer at http://127.0.0.1:8080/ui or http://localhost:8080/ui. Since 0.103 the
server answers only the names it is bound to (a DNS-rebinding defence); for any other name, add
--allow-host NAME. On loopback, token auth is the default since 0.107 (--auth token on other
binds): open the launch URL the command prints; it sets a session cookie, so later visits in that
browser need no token (see CLI.md). --auth none serves without a token.
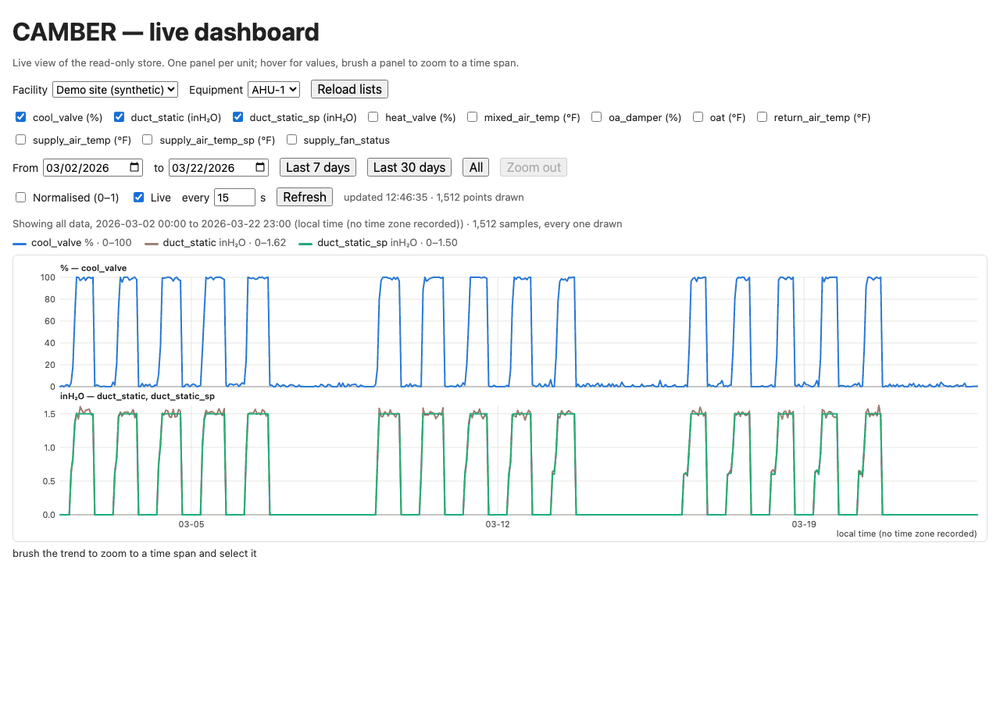
Synthetic data: the /ui trend viewer on a demo store, with one panel per unit (% and inH₂O) on a shared time axis. The store records no time zone for this facility, so the axis says so instead of claiming UTC.
Framework-free and dependency-light: stdlib http.server + inline vanilla JS/SVG, no framework, no
CDN, no external asset (a strict Content-Security-Policy header is sent on the HTML route). It is
read-only (GET-only) and binds 127.0.0.1 by default — exposing it on another interface is your
decision; it checks the Host header and uses token auth on loopback by default (--auth token
elsewhere), but no user
accounts or TLS (see SECURITY.md). The remaining nice-to-have is a live
carpet/heatmap panel; the live multitrend + selectors + cross-panel linking + polling ship now.
Units, axes and a legend (0.96, #78). Series of different scales no longer share one axis
(where CO₂ in ppm flattened a temperature or an airflow). The ticked series are drawn in one
panel per unit, each with a labelled y axis, on a shared time axis; a setpoint shares its
measurement's panel. The unit of each role comes from camber.api.ui.role_units() (the store
holds IP units: °F, cfm, inH₂O, %, ppm, kW, gpm, psig); counts carry a count unit (occupancy in
persons, the G36 request roles in requests, stage roles in stage), and a role with no unit the
viewer can state (a status, a mode, a command) gets its own panel. A legend
names each series with its unit and range, hovering shows every series' value at that time (none
inside a data gap), gaps in the data break the line, and Normalised (0–1) overlays every
series on one panel for comparing shapes. Still vanilla JS under the same CSP, with no external
asset.
Site time (0.96). The store holds each site's naive wall clock. When the facility's zone is
known, the time axis and the hover readout show that wall clock as site time, labelled with
the zone (e.g. local time (Australia/Sydney) since 0.103), and a UTC box converts both to
UTC. The zone comes from /facilities, whose rows carry a timezone key only when one is
recorded: a timezone on the facility's registry entry, or, for a catalog dataset, the zone it
was ingested into, or the zone an open-fdd ingest recorded. Config runs on a store source use the same lookup (0.100, #104).
Honest time axis (0.103, #122). Without a recorded zone the stored clock cannot be placed on
UTC, so the axis is labelled local time (no time zone recorded), the hover readout says the same,
and there is no UTC box. Before 0.103 that axis was labelled UTC although it showed the
publisher's local clock (most LBNL and ORNL datasets). With a zone the axis reads local time
(<zone>), and time (UTC) only while the UTC box is ticked. The page takes these labels from
/points?facility_id=…, whose reply carries a time_axis object: timezone (or null),
local_label, and utc_label (null when no zone is recorded).
Date range, zoom and fresh lists (0.103, #122). Before 0.103 the viewer drew each point's first 5,000 samples, so a long series showed only its start and series that began at different times showed different spans. Now:
- Whole span, thinned. The page opens on every sample of each ticked series, thinned on the
server to at most 2,000 per series. Each of 1,000 equal time buckets keeps its minimum and its
maximum sample, so a one-sample spike, a dip and a flatline all stay visible. A line under the
controls gives the span shown, its time-axis label, and how many samples were drawn out of how
many stored (
4,000 of 172,800 samples drawn (min and max of each time bucket kept)). - Date range. From and to dates, and Last 7 days, Last 30 days (counted back from the last stored sample, not from today) and All. A chosen window is read at full resolution, up to 20,000 samples per series; past that it is thinned the same way and the line says so. Dates are read in the clock the axis shows (site time, or UTC with the box ticked).
- Brush to zoom. Dragging across a panel zooms to that span, reads it again at full
resolution, and selects its samples: the
N selectedreadout under the chart counts them. Zoom out steps back through the spans viewed; All returns to the whole span. - Fresh lists. The facility and equipment lists are read again when either list is opened, on Reload lists or Refresh, and on each live poll, so a facility ingested after the page opened appears without a reload. The ticked roles and the chosen equipment are kept.
The read side behind this is /history's optional max_points parameter, the per-series budget
for that min/max envelope. Its reply also gives source_count (the rows in the window before
thinning), downsampled, and first / last (the window's first and last stored timestamp).
start and end name the store's wall clock; an offset on them is dropped, not converted, and a
malformed start, end, limit or max_points is a 400. A request without max_points returns
what it did before.
Scope
The static builders remain the dependency-light, self-contained artifact for reports and offline
sharing; the live /ui is for watching a running store. Agent narration on the live view is the
remaining item in the ROADMAP
Visualizations section.